The CPU is usually known as the brains of a pc, and identical to the human mind, it consists of a number of components that work collectively to course of data. Some take data in, some retailer it, some course of it, and others ship the outcomes again out. In immediately’s explainer, we’ll go over the important thing parts that make up a CPU and the way all of them work collectively to energy your laptop.
This text is a part of our Anatomy collection, which dissects the tech behind each main PC element. If you wish to go even deeper, our CPU Design collection covers how processors are designed and in-built way more technical element. This text goes over a few of these fundamentals at the next stage and brings them updated with how trendy CPUs truly work.
In comparison with different articles in our Anatomy collection (see the total record of {hardware} elements beneath), this one will inevitably be extra summary.
While you’re trying inside one thing like an influence provide, you’ll be able to clearly see the capacitors, transformers, and different elements. That is merely not potential with a contemporary CPU since every part is so tiny and since chipmakers like Intel, AMD, Apple and Qualcomm solely share their designs at a excessive stage. The precise circuitry is proprietary, so the matters lined on this article symbolize the final options that every one CPUs have.
You may need a PC at work or at residence. Possibly you utilize it to file tax returns, play the newest video games, and even construct and customise your personal system. However how effectively do you actually know the elements that make up a PC?
It is also value noting that what we name a “CPU” immediately is never only a CPU. Most trendy processors are nearer to a system-on-a-chip, packing built-in graphics, AI accelerators, reminiscence controllers and extra alongside the CPU cores.
It is also value noting that what we name a “CPU” immediately is never only a CPU.
Each digital system wants some type of a Central Processing Unit. Basically, a programmer writes code to do no matter their job is, after which a CPU executes that code to provide the supposed end result. The CPU can also be related to different components of a system like reminiscence and I/O to assist hold it fed with the related knowledge. Let’s dive in…
The CPU Blueprint
When analyzing any CPU, the very first thing you will come throughout is the Instruction Set Structure or ISA. That is the figurative blueprint for what a CPU can do and the way software program communicates with it. Identical to there are lots of breeds of canines throughout the identical species, there are lots of various kinds of ISAs a CPU could be constructed on.
The 2 commonest sorts are x86, which is most dominant in desktop PCs, laptops and servers, and Arm, which powers almost each smartphone and has unfold effectively past cell. Apple moved the Mac to its personal Arm chips in 2020, Qualcomm’s Snapdragon X processors introduced Arm to Home windows, and Arm designs now run a rising share of cloud and AI server chips from Amazon, Nvidia and Google.
There are others too. RISC-V, an open and royalty-free ISA, has grown from a distinct segment undertaking right into a severe contender. Billions of RISC-V cores already ship inside microcontrollers and the structure is slowly pushing into PCs, servers and AI chips. Older ISAs like MIPS and PowerPC have light into area of interest roles.
An ISA specifies what directions the CPU can course of, which registers software program can use, how reminiscence is addressed, and extra.
How a chip truly carries out these directions, together with its pipeline, caches and execution models, is known as the microarchitecture, and that is the place chipmakers compete.
AMD’s Zen 5 and Intel’s Lion Cove cores each run the identical x86 code, however they’re constructed very otherwise inside. ISAs additionally hold evolving: Intel and AMD fashioned an x86 Ecosystem Advisory Group in 2024 to coordinate future extensions to the structure.
To cowl the principle parts of a CPU, we’ll comply with the trail an instruction takes as it’s executed. Various kinds of directions could comply with completely different paths and use completely different components of a CPU, however we’ll generalize right here to cowl the largest components.
We’ll begin with probably the most primary design of a single-core processor and steadily add complexity as we get in direction of a extra trendy design.
Management Unit and Datapath
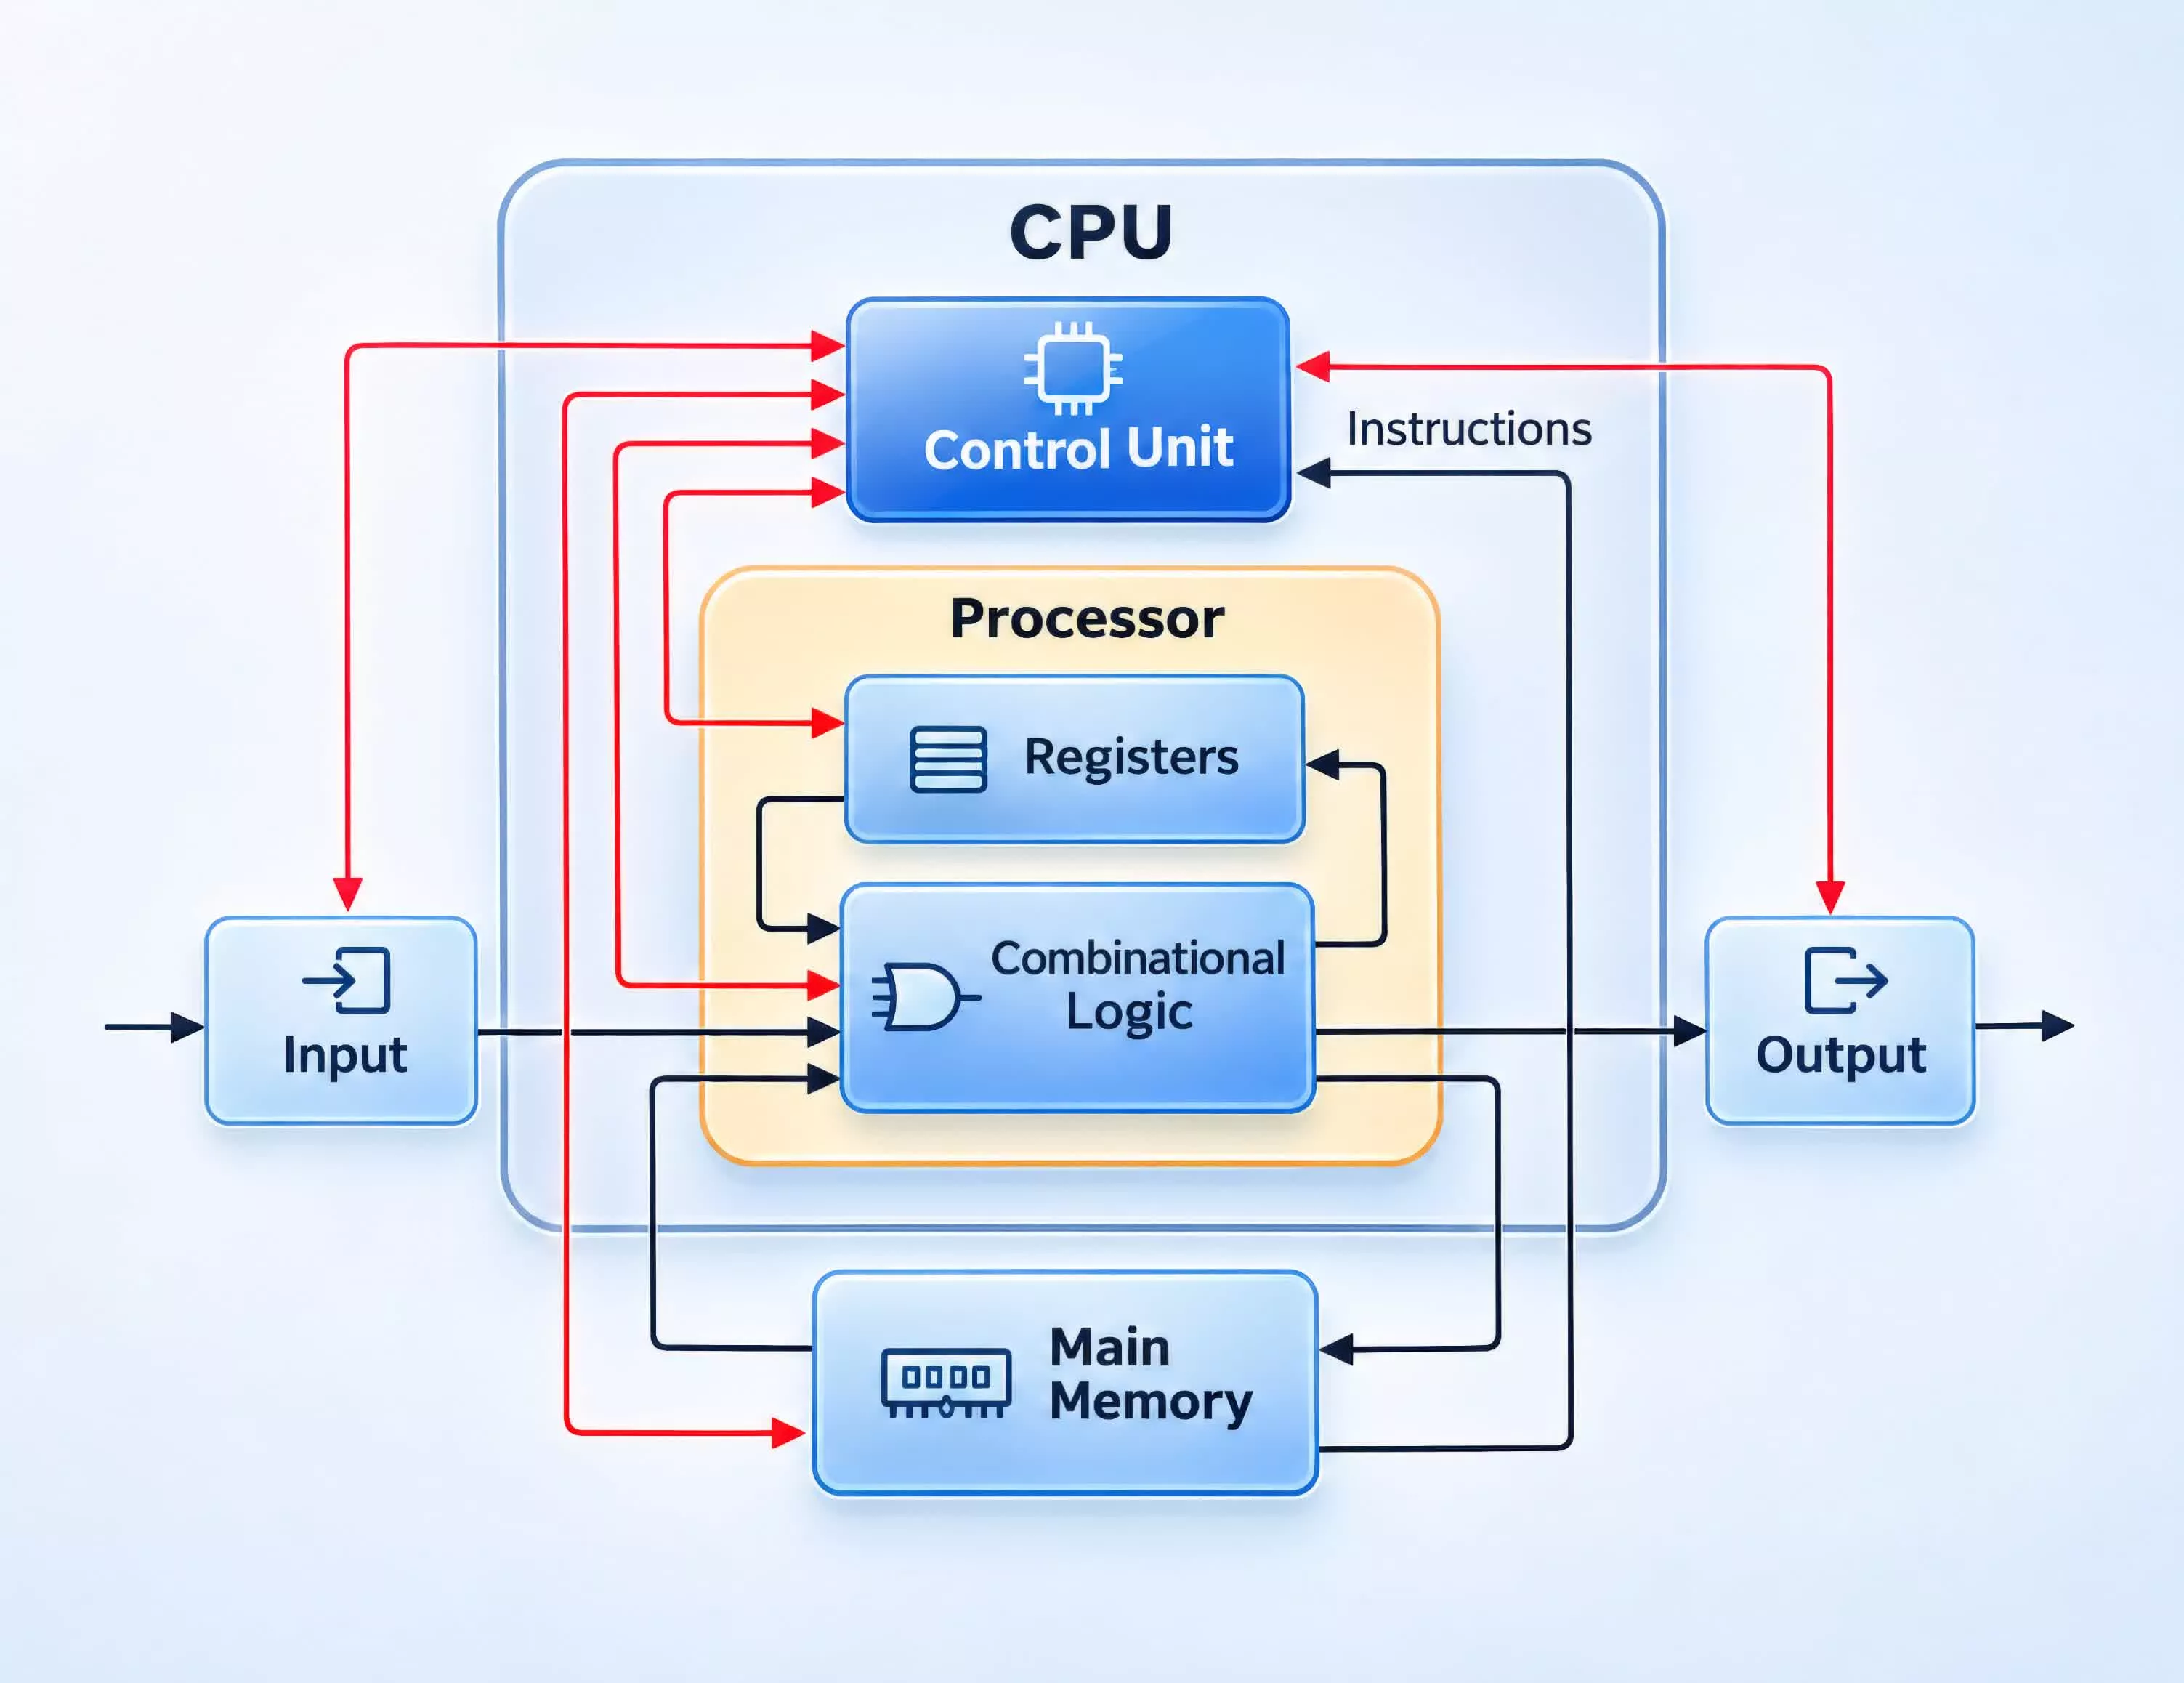
Block diagram of a primary CPU. Black strains point out knowledge movement, purple strains point out management movement.
The components of a CPU could be divided into two: the management unit and the datapath. Think about a prepare. The engine is what strikes the prepare, however the engineer is pulling the levers behind the scenes and controlling the completely different elements of the engine. A CPU is identical means.
The datapath is just like the engine and, because the identify suggests, is the trail the place the info flows as it’s processed. The datapath receives the inputs, processes them, and sends them out to the precise place when they’re performed. The management unit tells the datapath the way to function, just like the engineer driving the prepare. Relying on the instruction, the management unit will route indicators to completely different elements, activate and off completely different components of the datapath, and monitor the state of the CPU.
The Instruction Cycle: Fetch
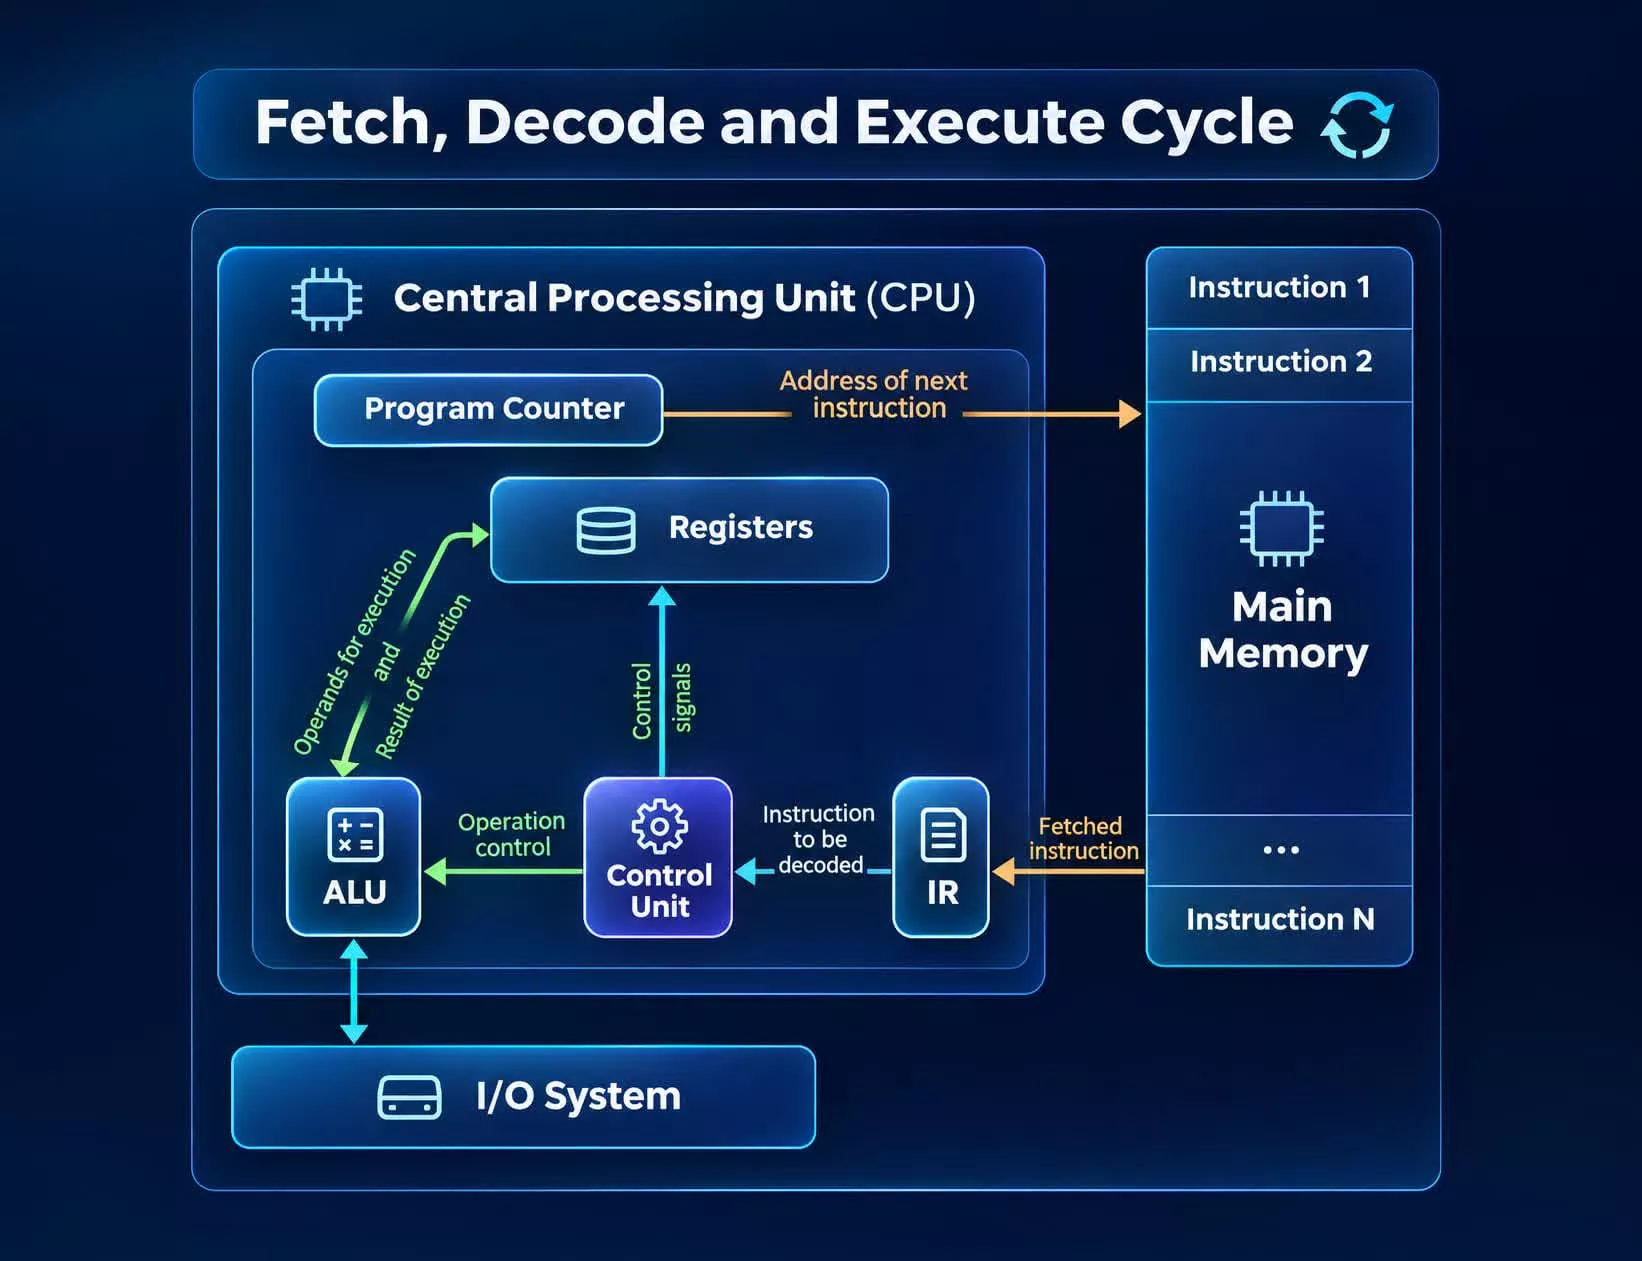
The very first thing our CPU should do is work out what directions to execute subsequent and switch them from reminiscence into the CPU. Directions are usually produced by a compiler and are particular to the CPU’s ISA. ISAs will share commonest varieties of directions like load, retailer, add, subtract, and many others., however there could also be further particular varieties of directions distinctive to every specific ISA. The management unit will know what indicators have to be routed the place for every sort of instruction.
While you run a .exe on Home windows, for instance, the code for that program is moved into reminiscence and the CPU is informed what tackle the primary instruction begins at. The CPU all the time maintains an inner register that holds the reminiscence location of the following instruction to be executed. That is known as the Program Counter (PC).
As soon as it is aware of the place to begin, step one of the instruction cycle is to get that instruction. This strikes the instruction from reminiscence into the CPU’s instruction register and is named the Fetch stage. Realistically, the instruction is more likely to be within the CPU’s cache already, however we’ll cowl these particulars in a bit.
In follow, trendy CPUs do not fetch one instruction at a time. They seize a block of dozens of bytes each cycle, which may maintain a number of directions without delay. The fetch unit would not wait to be informed the place to go subsequent both. A department predictor, which we’ll cowl later, continuously guesses the place this system is headed and steers fetching forward of time so the remainder of the CPU is rarely left ready for work.
The Instruction Cycle: Decode
When the CPU has an instruction, it wants to determine particularly what sort of instruction it’s. That is known as the Decode stage. Every instruction could have a sure set of bits known as the Opcode that tells the CPU the way to interpret it. That is much like how completely different file extensions are used to inform a pc the way to interpret a file. For instance, .jpg and .png are each picture recordsdata, however they manage knowledge otherwise so the pc must know the kind in an effort to correctly interpret them.
Relying on how complicated the ISA is, the instruction decode portion of the CPU could get complicated. RISC-V’s base instruction set has just a few dozen directions (optionally available extensions add extra), whereas x86 has effectively over a thousand, many with a number of variants. x86 directions additionally differ in size from 1 to fifteen bytes, so the CPU has to work out the place one instruction ends and the following begins earlier than it will probably even decode them.
That makes decoding one of the vital difficult components of an x86 CPU from Intel or AMD, and one which takes up numerous house. Arm directions, against this, are a hard and fast 4 bytes, which is one cause Apple’s cores can decode eight or extra directions per cycle.
To ease the burden, x86 CPUs break complicated directions down into easier inner operations known as micro-ops, and retailer just lately decoded micro-ops in a devoted micro-op cache.
When the identical code runs once more, which occurs continuously in loops, the CPU can skip the decoders solely. Intel has used this trick since Sandy Bridge in 2011, and AMD because the authentic Zen in 2017.
The most typical varieties of directions {that a} CPU would decode are reminiscence, arithmetic or department directions.
3 Most important Instruction Sorts
A reminiscence instruction could also be one thing like “learn the worth from reminiscence tackle 1234 into worth A” or “write worth B to reminiscence tackle 5678.”
An arithmetic instruction is perhaps one thing like “add worth A to worth B and retailer the end result into worth C.”
A department instruction is perhaps one thing like “execute this code if worth C is constructive or execute that code if worth C is adverse.”
A typical program could chain these collectively to give you one thing like “add the worth at reminiscence tackle 1234 to the worth at reminiscence tackle 5678 and retailer it in reminiscence tackle 4321 if the result’s constructive or at tackle 8765 if the result’s adverse.”
Earlier than we begin executing the instruction we simply decoded, we have to pause for a second to speak about registers… a CPU has a couple of very small however very quick items of reminiscence known as registers. On a 64-bit CPU, the general-purpose registers maintain 64 bits every, and there are solely a handful of them: 16 on x86 and 31 on Arm. CPUs even have wider vector registers, as much as 512 bits every, used to course of many values without delay.
These are used to retailer values which are at present getting used and could be considered the very prime of the reminiscence hierarchy (an “L0 cache” or kinds), even quicker than the L1 cache. Within the instruction examples above, values A, B, and C would all be saved in registers.
These are the registers software program can see. Behind the scenes, trendy CPUs hold tons of of bodily registers and use a method known as register renaming to map them to the few that applications use.
This lets the CPU work on many directions without delay with out them overwriting one another’s values, which turns into necessary after we get to out-of-order execution.
Execute and the ALU
Again to the execution stage now. This can be completely different for the three varieties of directions we talked about above, so we’ll cowl each individually.
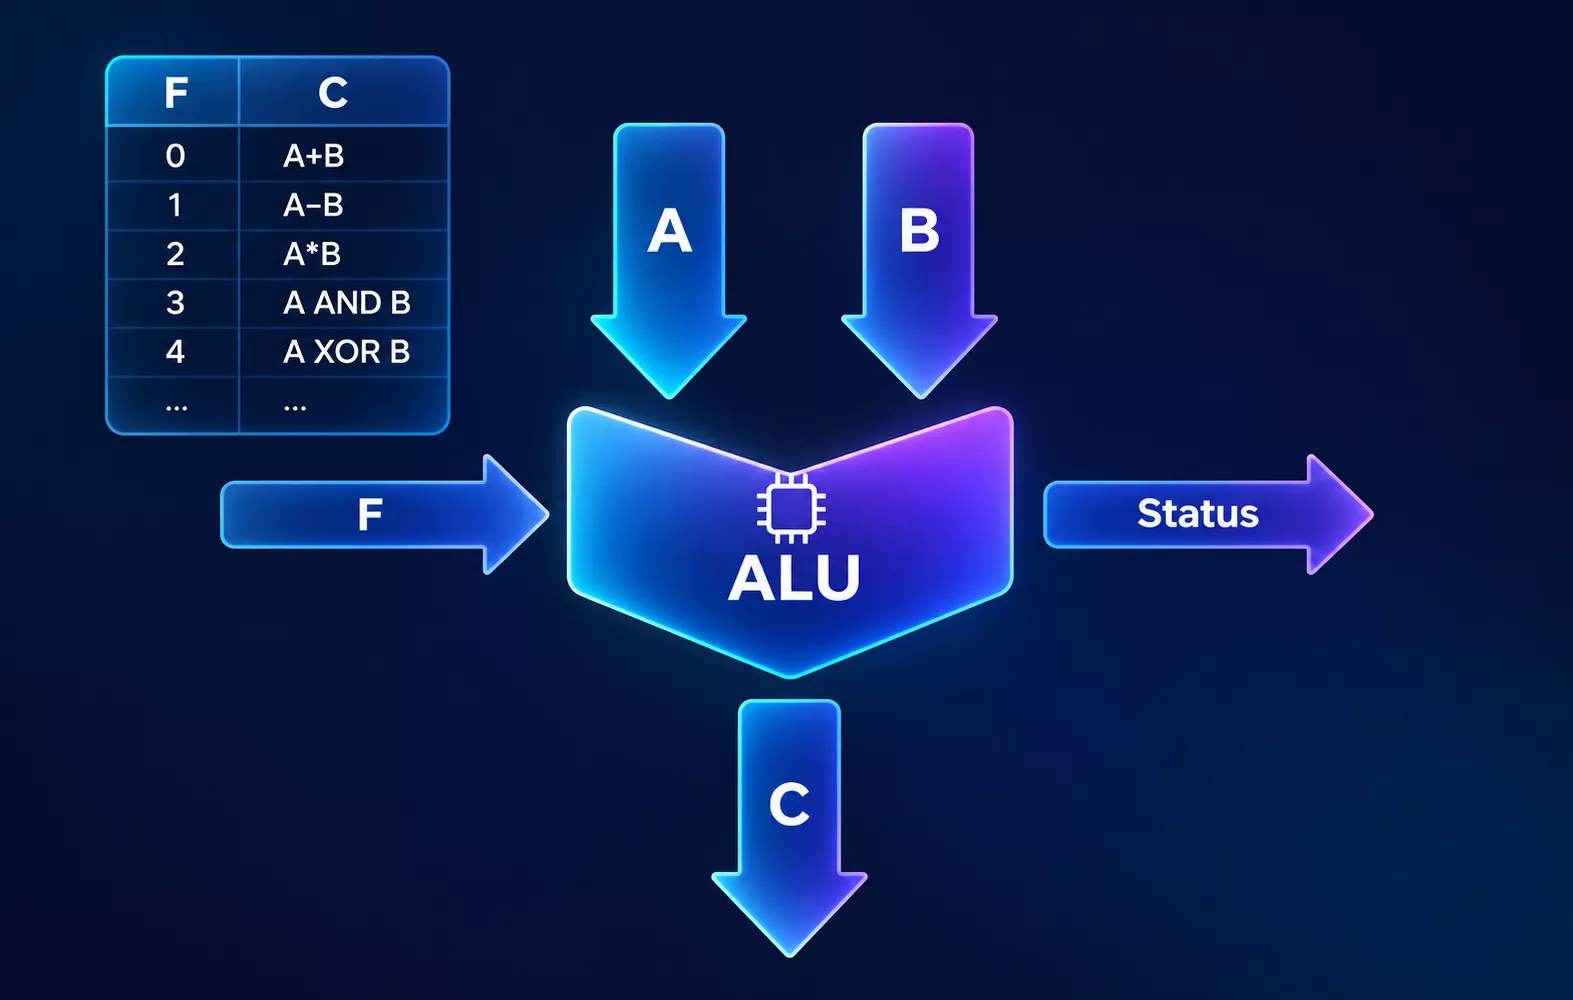
We’ll begin with arithmetic directions since they’re the best to know. Some of these directions are fed into an Arithmetic Logic Unit (ALU) for processing. An ALU is a circuit that usually takes two inputs with a management sign and outputs a end result.
Think about a primary calculator you utilized in center college. To carry out an operation, you sort within the two enter numbers in addition to what sort of operation you wish to carry out. The calculator does the computation and outputs the end result.
Within the case of our CPU’s ALU, the kind of operation is decided by the instruction’s opcode and the management unit would ship that to the ALU. Along with primary arithmetic, ALUs also can carry out bitwise operations like AND, OR, NOT, and XOR. The ALU will even output some standing information for the management unit in regards to the calculation it has simply accomplished. This might embrace issues like whether or not the end result was constructive, adverse, zero, or had an overflow.
That is an enormous a part of why trendy CPUs are a lot quicker than older ones working at comparable clock speeds.
A contemporary CPU core would not have only one ALU. Excessive-end designs have half a dozen or extra integer ALUs working in parallel, plus separate models for floating-point math and vector directions, which may apply the identical operation to an entire batch of numbers without delay. That is an enormous a part of why trendy CPUs are a lot quicker than older ones working at comparable clock speeds.
An ALU is most related to arithmetic operations, however it could even be used for reminiscence or department directions. For instance, the CPU could have to calculate a reminiscence tackle given as the results of a earlier arithmetic operation.
It could additionally have to calculate the offset so as to add to this system counter {that a} department instruction requires. One thing like “if the earlier end result was adverse, leap forward 20 directions.” In trendy CPUs, reminiscence tackle calculations are normally handed off to devoted “AGUs” or Tackle Era Items, however the precept is identical.
Reminiscence and the Cache Hierarchy
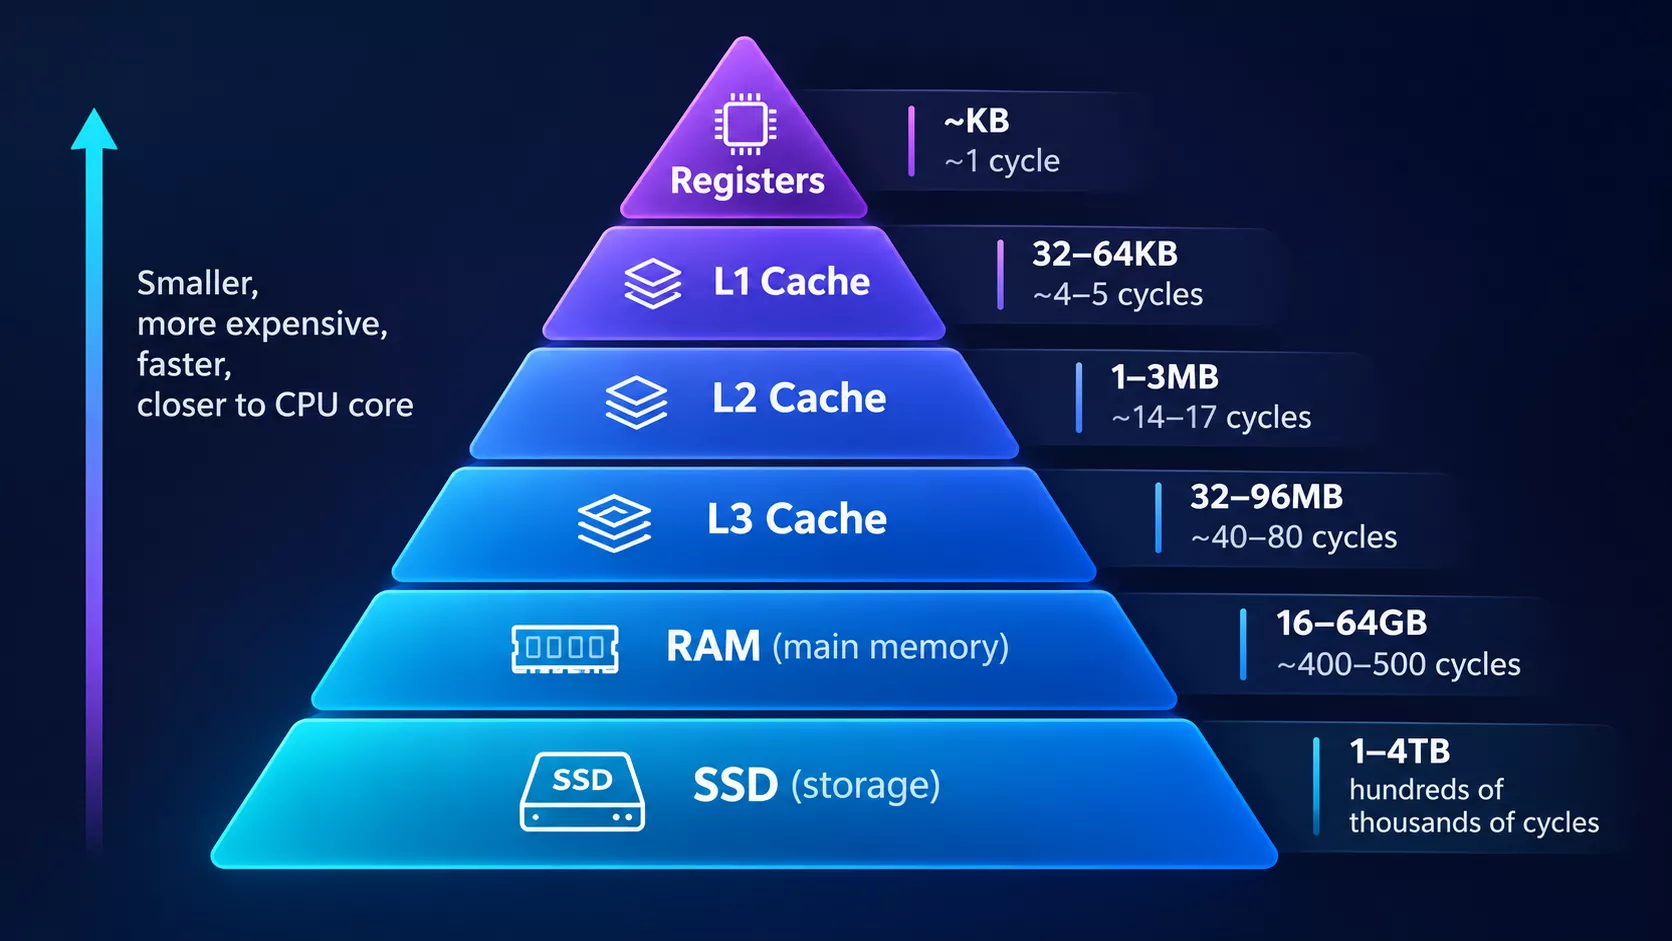
For reminiscence directions, we’ll want to know an idea known as the Reminiscence Hierarchy. This represents the connection between caches, RAM, and fundamental storage.
When a CPU receives a reminiscence instruction for a bit of knowledge that it would not but have regionally in its registers, it is going to go down the reminiscence hierarchy till it finds it. Most trendy CPUs include three ranges of cache: L1, L2, and L3, and a few current designs add a fourth.
The primary place the CPU will examine is the L1 cache. That is the smallest and quickest stage. The L1 cache is usually break up right into a portion for knowledge and a portion for directions. Bear in mind, directions have to be fetched from reminiscence identical to knowledge.
A typical L1 cache is tiny, normally 32 to 64KB every for knowledge and directions per core. If the CPU cannot discover what it is searching for within the L1 cache, it is going to examine the L2 cache. That is normally 1 to 3MB per core on present desktop chips.
The following step is the L3 cache, which can be a couple of tens of MB and is shared between cores. AMD’s X3D chips stack an additional 64MB of L3 immediately on prime of the processor, which is why they’re so sturdy in video games, a workload that advantages vastly from extra cache.
If the CPU cannot discover the info it wants within the L3 cache, it is going to go to RAM. If the info is not in RAM both, the working system has to load it from storage, which is much slower nonetheless. As we go down every step, the out there house will increase by roughly an order of magnitude, however so does the latency.
As soon as the CPU finds the info, it is going to deliver it up the hierarchy in order that the CPU has quick entry to it if wanted sooner or later. There are numerous steps right here, however it ensures that the CPU has quick entry to the info it wants.
For instance, the CPU can learn from its inner registers in only a cycle or two, L1 in a handful of cycles, L2 in a dozen or extra, and the L3 in a couple of dozen. Going out to RAM takes a number of hundred cycles, and fetching from an SSD takes tons of of 1000’s. A tough drive can take thousands and thousands.
Every core usually has its personal personal L1 and L2 caches, whereas the L3 is shared amongst a bunch of cores, such because the eight cores on one among AMD’s Zen 5 chiplets. Intel’s effectivity cores are an exception, sharing an L2 cache in clusters of 4. We’ll discuss extra about multi-core CPUs later on this article.
Branches, Pipelining and Prediction
The final of the three main instruction sorts is the department instruction. Trendy applications leap round on a regular basis and a CPU will hardly ever ever execute greater than a dozen contiguous directions with out a department.
Department directions come from programming parts like if-statements, for-loops, perform calls, and return-statements. These are all used to interrupt this system execution and change to a special a part of the code. There are additionally leap directions, that are department directions which are all the time taken.
Conditional branches are particularly tough for a CPU since it could be executing a number of directions without delay and will not decide the result of a department till after it has began on subsequent directions.
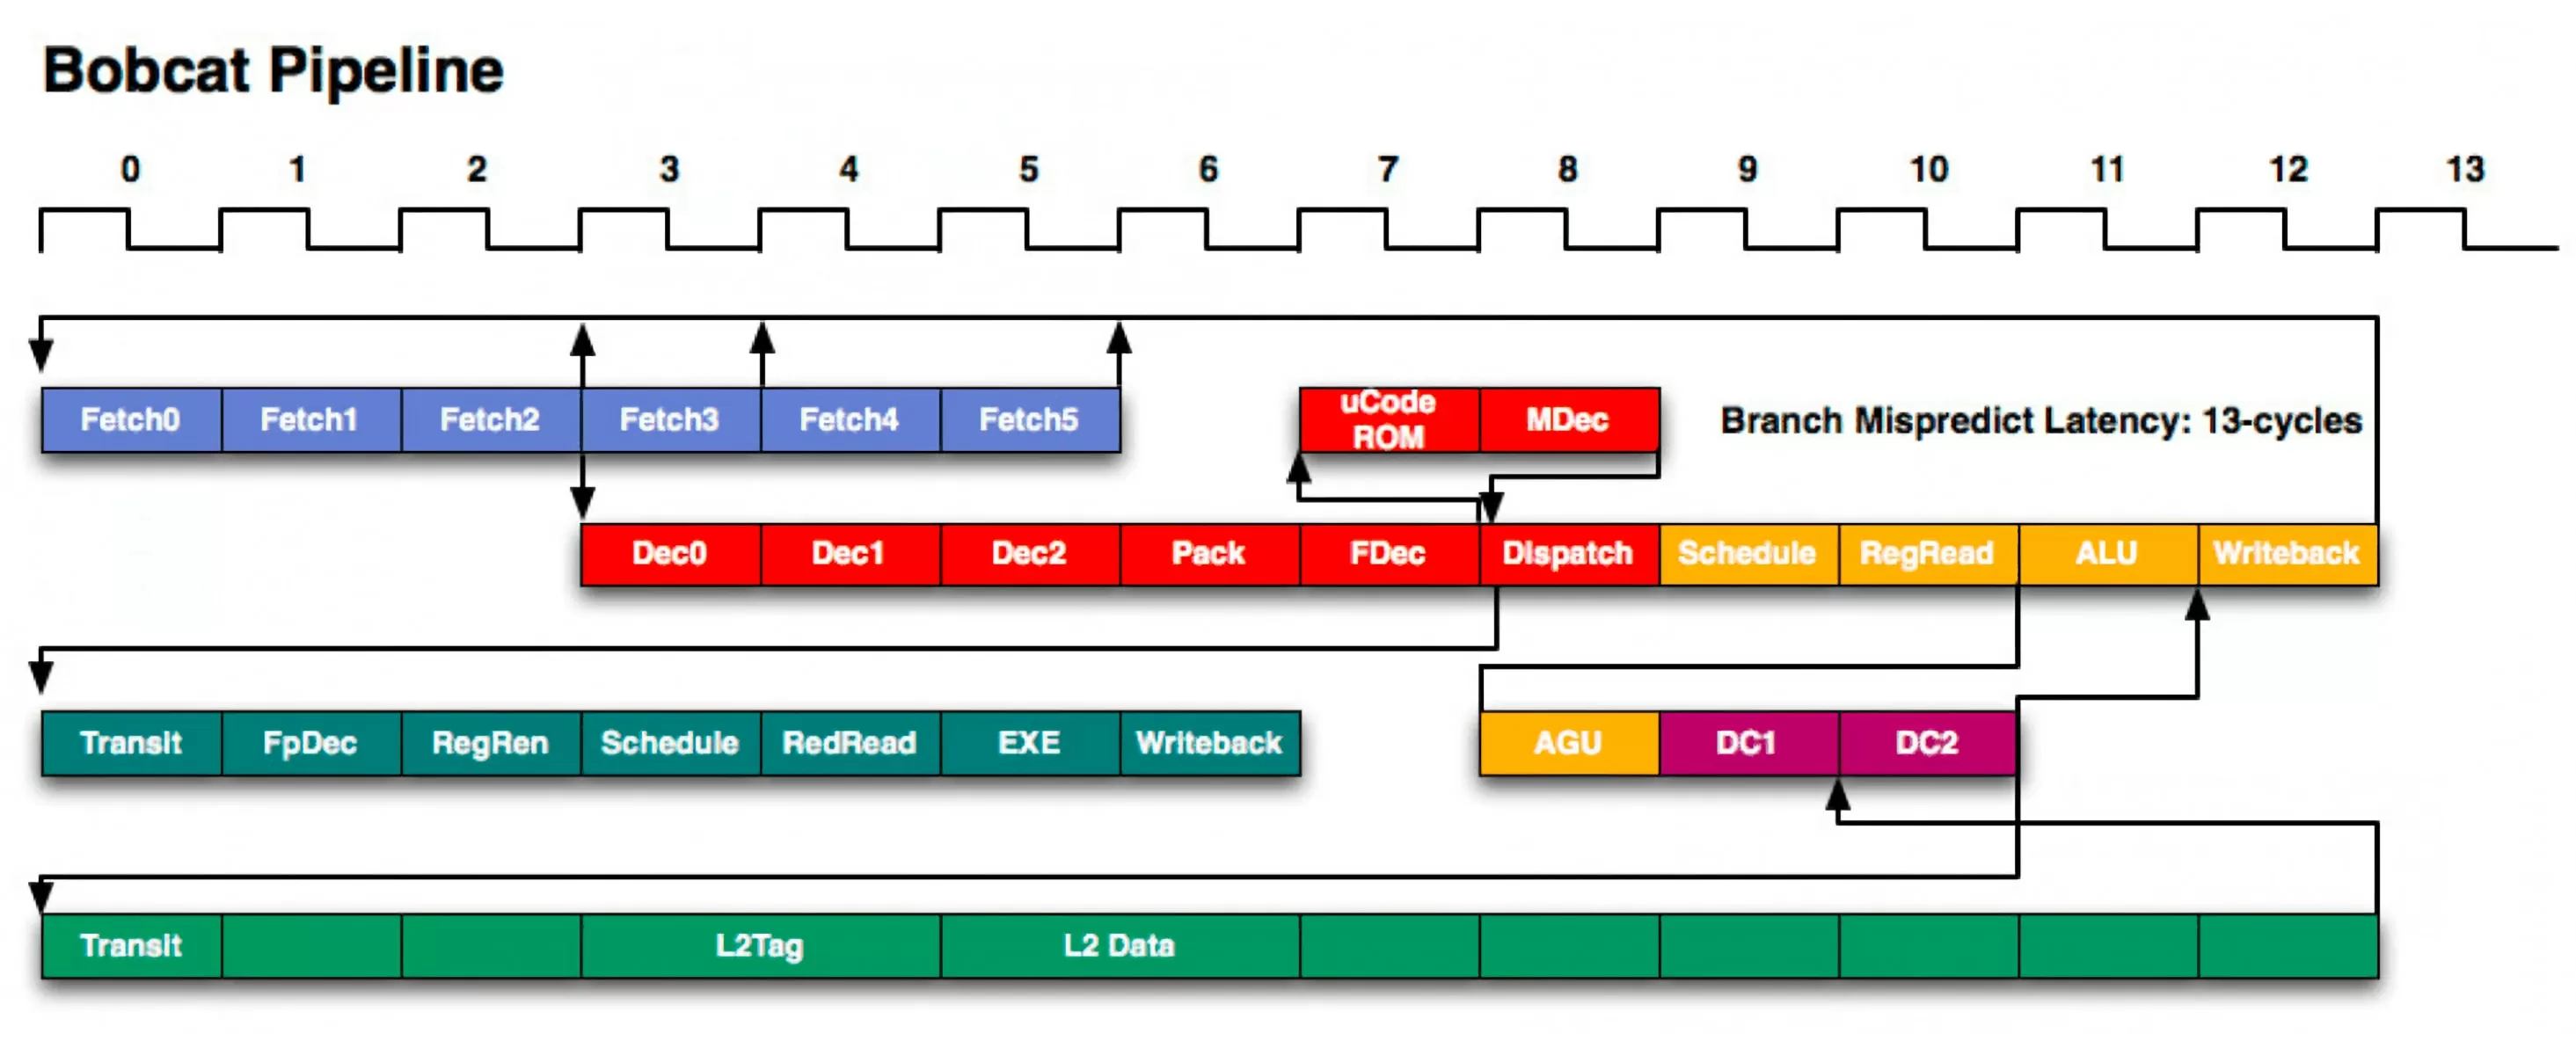
So as to absolutely perceive why this is a matter, we’ll have to take one other diversion and speak about pipelining. Every step within the instruction cycle could take a couple of cycles to finish. That signifies that whereas an instruction is being fetched, the ALU would in any other case be sitting idle. To maximise a CPU’s effectivity, we overlap the phases of various directions in a course of known as pipelining.
The traditional option to perceive that is by way of an analogy to doing laundry. You could have two hundreds to do and washing and drying every take an hour. You can put the primary load within the washer after which the dryer when it is performed, after which begin the second load. This might take 4 hours. Nonetheless, in the event you divided the work and began the second load washing whereas the primary load was drying, you might get each hundreds performed in three hours.
The one-hour discount scales with the variety of hundreds you have got and the variety of washers and dryers. It nonetheless takes two hours to do a person load, however the overlap will increase the whole throughput from 0.5 hundreds/hr to about 0.67 hundreds/hr, and with sufficient hundreds it approaches one load per hour.
The pipeline of AMD’s low-power Bobcat core from 2011. Even a comparatively easy design like this one has greater than a dozen phases.
CPUs use this identical technique to enhance instruction throughput. A contemporary Arm or x86 core usually has someplace between 10 and 20 pipeline phases. And since trendy cores additionally deal with a number of directions per stage and execute them out of order, a high-end core can have tons of of directions in flight at any given second. Every design is exclusive, however one pattern division could also be 4 cycles for fetch, 6 cycles for decode, 3 cycles for execute, and seven cycles for writing again the outcomes and retiring the instruction.
Again to branches, hopefully you can begin to see the difficulty. If we do not know that an instruction is a department till cycle 10, we could have already began executing 9 new directions which may be invalid if the department is taken. To get round this concern, CPUs have very complicated constructions known as department predictors.
Some even borrow strategies from machine studying, equivalent to easy neural networks known as perceptrons, to guess whether or not a department can be taken or not. The intricacies of department predictors are effectively past the scope of this text, however on a primary stage, they observe the standing of earlier branches to be taught whether or not or not an upcoming department is more likely to be taken.
Trendy department predictors are proper effectively over 95% of the time on typical code, and so they work to date forward that they usually guess the place a program goes earlier than the department instruction has even been decoded.
As soon as the results of the department is thought for certain (it is completed that stage of the pipeline), this system counter can be up to date and the CPU will go on to execute the following instruction. If the department was mispredicted, the CPU will throw out all of the directions after the department that it mistakenly began to execute and begin up once more from the proper place.
With so many directions in flight, every fallacious guess wastes numerous work, which is why chipmakers hold pouring transistors into higher predictors.
Out-of-Order Execution
Now that we all know the way to execute the three commonest varieties of directions, let’s check out among the extra superior options of a CPU. Just about all trendy processors do not truly execute directions within the order wherein they’re obtained.
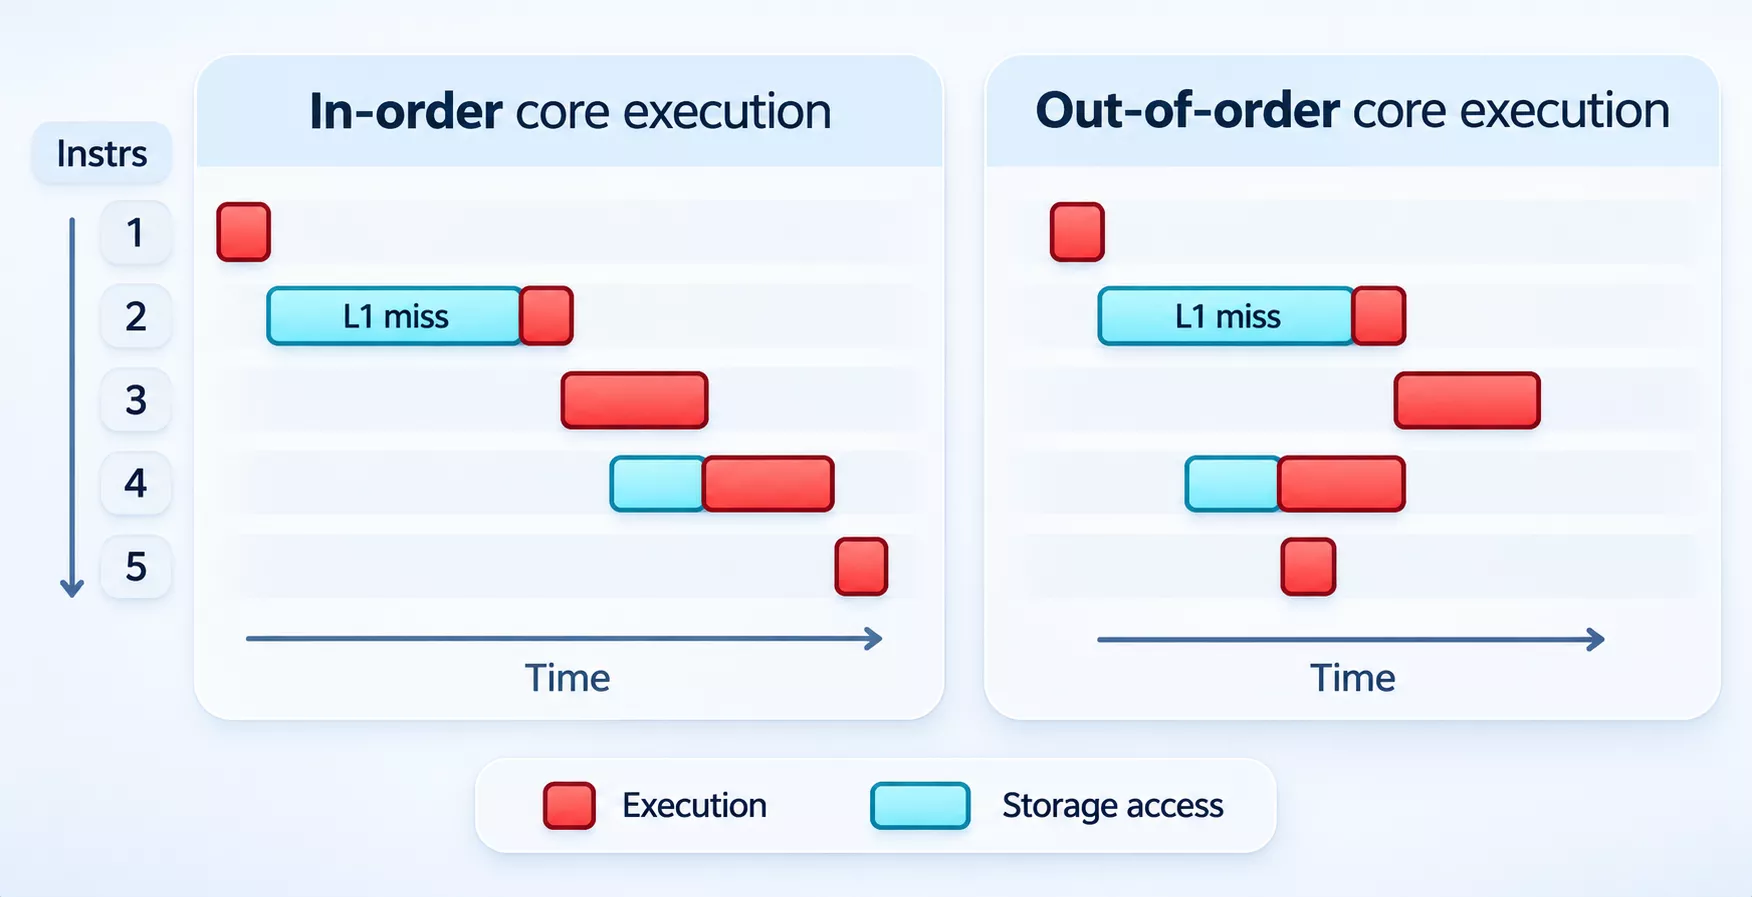
A paradigm known as out-of-order execution is used to attenuate downtime whereas ready for different directions to complete.
If a CPU is aware of that an upcoming instruction requires knowledge that will not be prepared in time, it will probably change the instruction order and herald an unbiased instruction from later in this system whereas it waits. To maintain this from breaking this system, the CPU tracks each instruction in a construction known as the reorder buffer.
Directions can end in any order, however their outcomes are solely made remaining (“retired”) within the authentic program order, so from the software program’s viewpoint, every part occurred precisely as written. That is additionally the place the register renaming we talked about earlier pays off, letting unbiased directions run aspect by aspect with out stepping on one another’s values. This instruction reordering is an especially highly effective software, however it’s removed from the one trick CPUs use.
One other efficiency enhancing characteristic is known as prefetching. In the event you had been to time how lengthy it takes for a random instruction to finish from begin to end, you’d discover that the reminiscence entry takes up more often than not. A prefetcher is a unit within the CPU that watches the sample of reminiscence accesses and tries to foretell what knowledge this system will want subsequent.
If a program is studying by way of reminiscence in a predictable means, equivalent to stepping by way of a big array, the prefetcher will attain out to RAM and pull that knowledge into the cache earlier than it is requested. Therefore the identify pre-fetch.
Speculative Execution and Safety
Department prediction and out-of-order execution have a aspect impact value realizing about. When a CPU guesses which means a department will go, it would not simply fetch these directions. It executes them speculatively and throws the outcomes away if the guess was fallacious. For many years, that was thought of innocent.
That modified in 2018 with the disclosure of Spectre and Meltdown, two households of vulnerabilities that confirmed discarded speculative work nonetheless leaves traces behind, primarily within the cache. By rigorously measuring how lengthy reminiscence accesses take, an attacker may infer knowledge the CPU was by no means imagined to reveal, equivalent to passwords or encryption keys from one other program. Just about each high-performance CPU from Intel, AMD and Arm was affected to some extent.
Meltdown has since been fastened in {hardware}, however Spectre-style assaults are an entire class of issues reasonably than a single bug, and new variants proceed to floor yearly.
Chipmakers now design their cores with these aspect channels in thoughts, and among the software program mitigations include a efficiency value. It is a good instance of how the identical options that make trendy CPUs quick also can make them tougher to safe.
Accelerators and AI
One other main characteristic now routinely included in CPUs is task-specific accelerators. These are circuits whose whole job is to carry out one small job as quick as potential. This may embrace encryption, media encoding, or machine studying.
The CPU can do this stuff by itself, however it’s vastly extra environment friendly to have a unit devoted to them. An awesome instance of that is graphics. Certainly the CPU can carry out the computations wanted for graphics processing, however having a devoted unit for them (an built-in GPU) affords orders of magnitude higher efficiency.
A giant addition in recent times is the NPU, or Neural Processing Unit, a block constructed particularly to run AI workloads like dwell transcriptions or native language fashions whereas sipping energy. NPUs went from just about nonexistent in PCs to a near-standard characteristic in simply a few years.
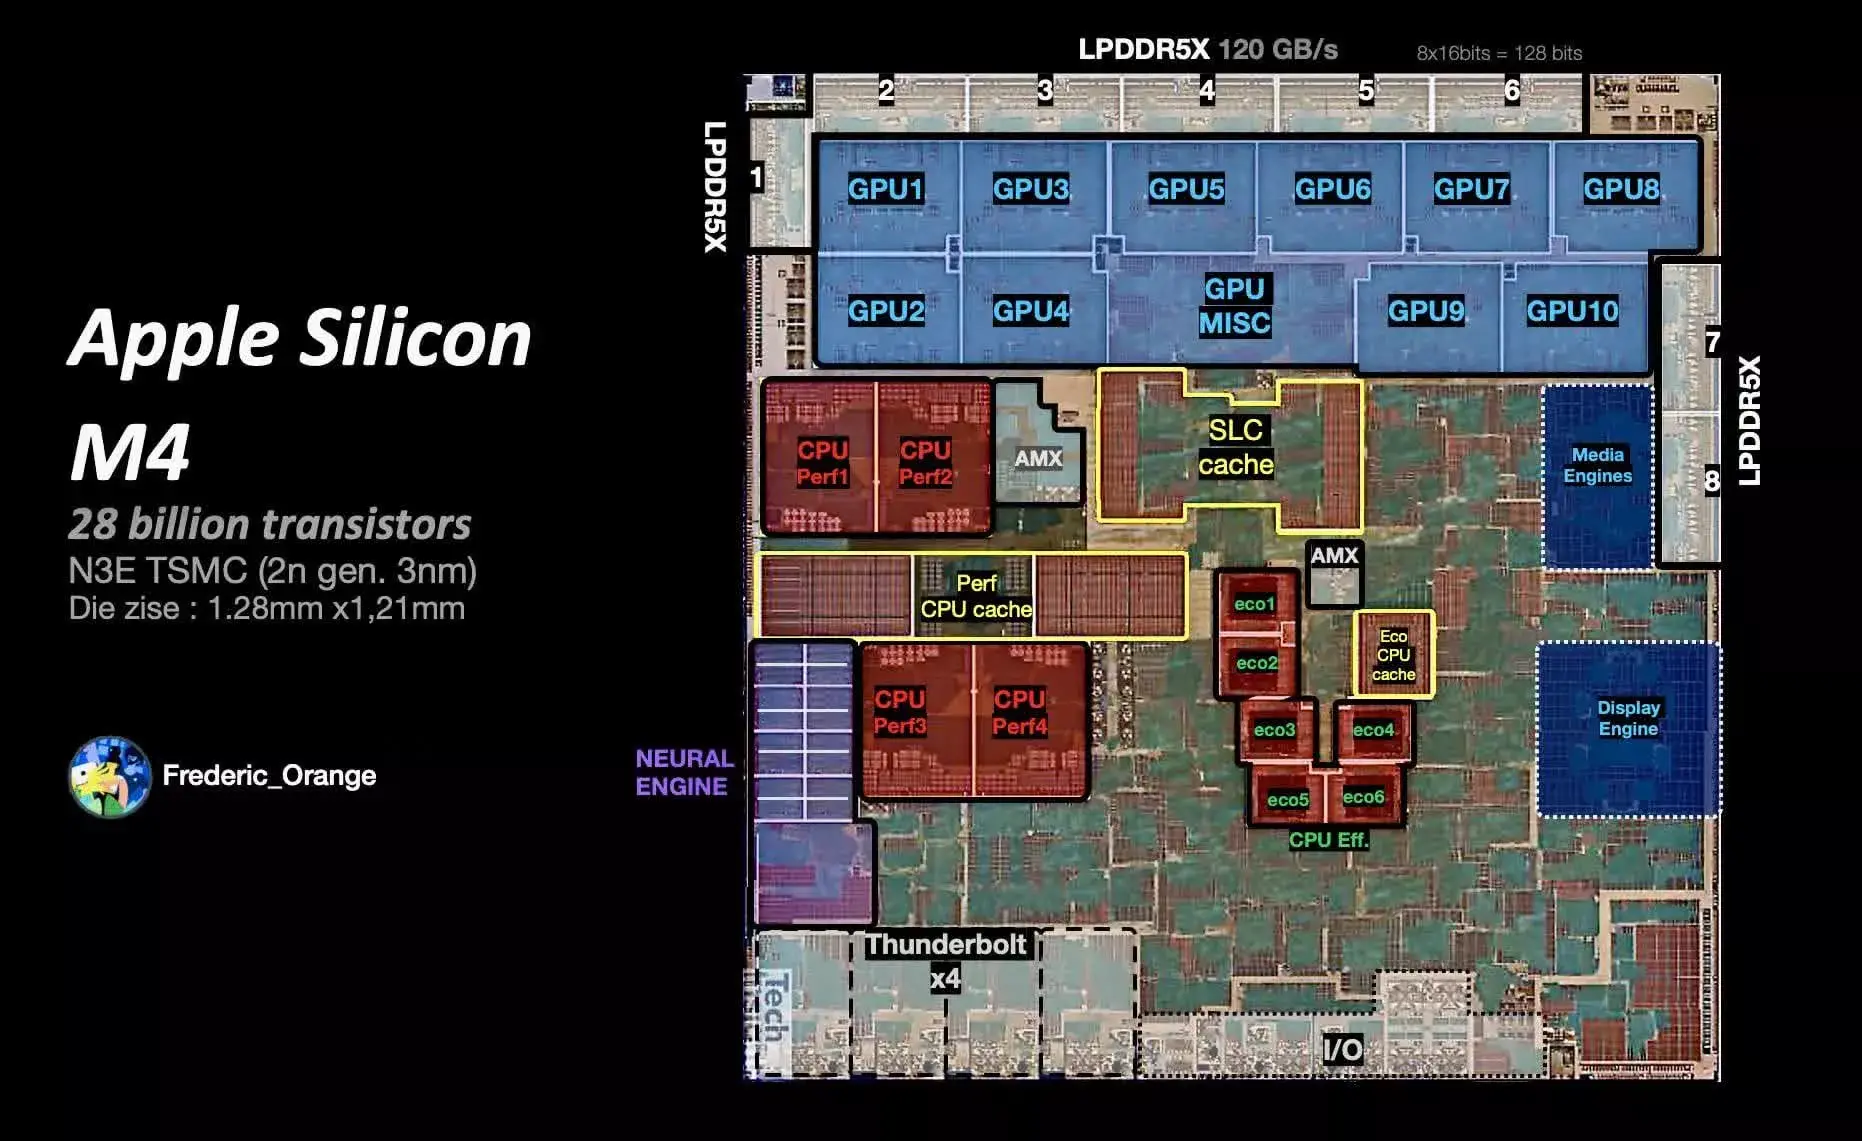
The CPU cores themselves have additionally gained extra specialised {hardware}. Broad vector extensions like AVX-512 can crunch 16 numbers in a single instruction, and newer matrix extensions, equivalent to Intel’s AMX on server chips and Arm’s SME present in Apple’s M4, are designed particularly to speed up AI math.
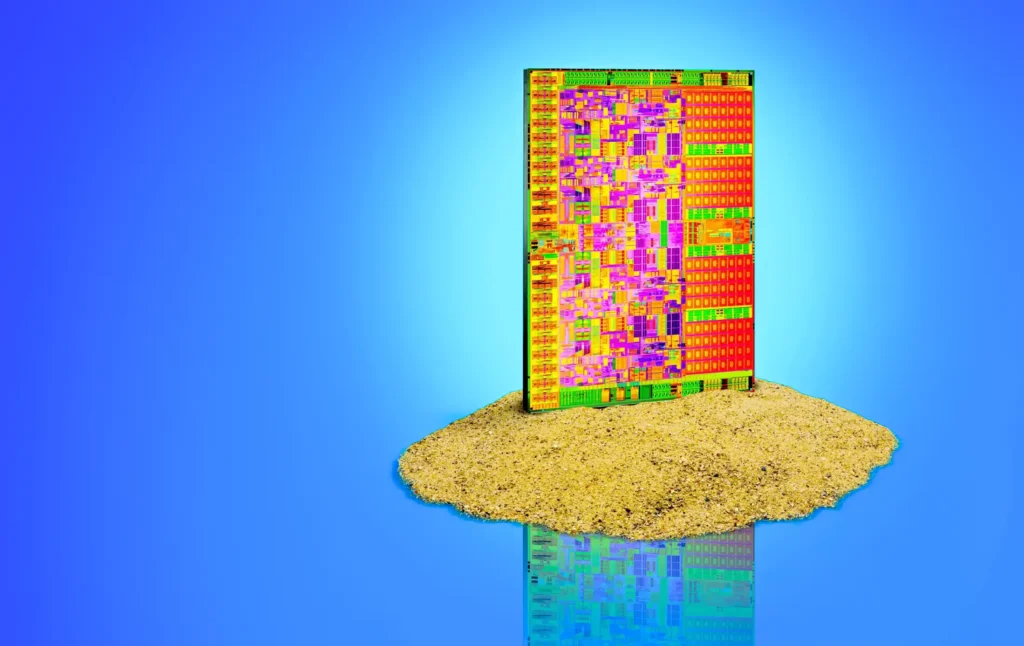
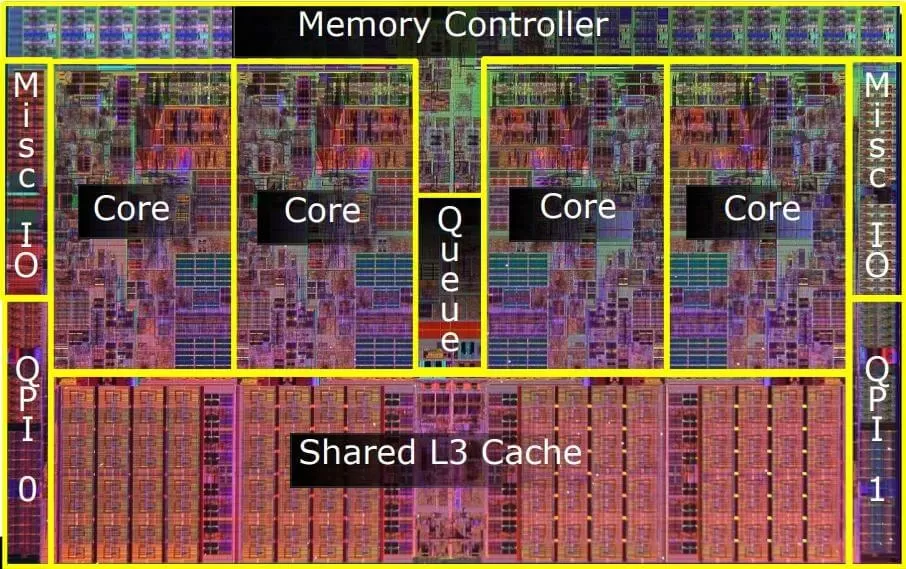
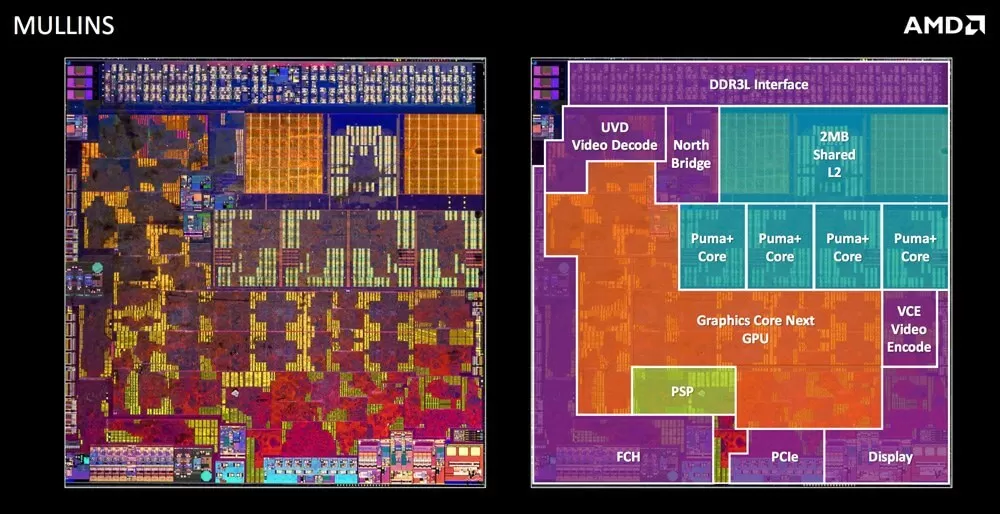
The image beneath reveals an Intel CPU from 2008. Many of the house is taken up by cores and cache. The second image reveals an AMD “Mullins” cell APU. Many of the house there may be taken up by elements aside from the cores.
Above: the die of Intel’s first era Nehalem structure. Word that the cores and cache take up the vast majority of the house. Under: The die of an AMD SoC exhibiting the massive quantity of house dedicated to accelerators and exterior interfaces.
Devoted media engines deal with video encoding and decoding, together with the AV1 codec, so recording or streaming barely touches the cores.
With the rise of accelerators, the CPU cores could solely take up a fraction of the chip, particularly in laptop computer processors the place the GPU, NPU and media engines are all built-in alongside them.
Going Multicore
The final main characteristic to cowl is how we will join a bunch of particular person CPUs collectively to type a multicore CPU. It is not so simple as simply placing a number of copies of the one core design we talked about earlier. Identical to there isn’t any straightforward option to flip a single-threaded program right into a multi-threaded program, the identical idea applies to {hardware}. The problems come from dependence between the cores.
The cores do not every get their very own path to RAM. As a substitute, they’re linked by an on-chip interconnect, equivalent to a hoop or a mesh, that connects them to one another, to the shared L3 cache, and to the reminiscence controllers.
With a number of entities working on probably the identical items of knowledge, points like coherence and consistency have to be resolved. If two cores had been each processing directions that used the identical knowledge, how do they know who has the precise worth? What if one core modified the info however it did not attain the opposite core in time for it to execute? Since they’ve separate caches which will retailer overlapping knowledge, complicated algorithms and controllers have to be used to take away these conflicts.
Sometimes, separate cores will course of instruction streams from completely different threads. This helps cut back the dependence between cores. That is why in the event you examine Activity Supervisor, you will usually see a couple of cores working arduous whereas the others are hardly working. Many applications nonetheless aren’t designed for multithreading, or solely break up their work throughout a handful of threads. There may make sure circumstances the place it is extra environment friendly to have one core do the work reasonably than pay the overhead penalties of attempting to divide up the work.
Simultaneous Multithreading
Many CPUs additionally let a single core work on two threads without delay, a method known as simultaneous multithreading (SMT), which Intel manufacturers as Hyper-Threading. Since even one of the best out-of-order core cannot hold all of its execution models busy on a regular basis, a second thread can fill within the gaps.
It usually provides 10 to 30% extra throughput in well-threaded workloads for little or no further die house. SMT has lengthy been a staple of contemporary CPUs, however Intel just lately dropped Hyper-Threading from the efficiency cores in its Lunar Lake and Arrow Lake chips, opting to spend that effort on making every core quicker and extra environment friendly as a substitute. Apple and Qualcomm do not use SMT in any respect.
Hybrid Architectures
For years, each core in a desktop CPU was similar. That is now not a given. Borrowing the thought from how smartphone chips work, many processors combine massive and quick efficiency cores (normally known as P-cores) with smaller and extra power-efficient cores (E-cores).
Some current laptop computer chips add a 3rd tier of low-power cores for mild background duties as effectively. Intel adopted this strategy with Alder Lake in 2021, and Apple and Qualcomm do one thing comparable. In the meantime, AMD builds compact “c” variations of its Zen cores that commerce peak clock velocity for measurement and effectivity.
The catch is that the working system must know which core is finest for which job. Intel’s Thread Director, for instance, feeds hints to Home windows about what every thread is doing, so a sport lands on the P-cores whereas background updates are despatched to the E-cores.
Chiplets and Tiles
The opposite massive shift is in how CPUs are bodily constructed. We wrote a whole technical explainer in regards to the significance of chiplets some time again. The thought is that as a substitute of constructing one massive piece of silicon, each AMD and Intel now break up their processors into smaller dies, which AMD calls chiplets and Intel calls tiles, and join them inside the identical bundle.
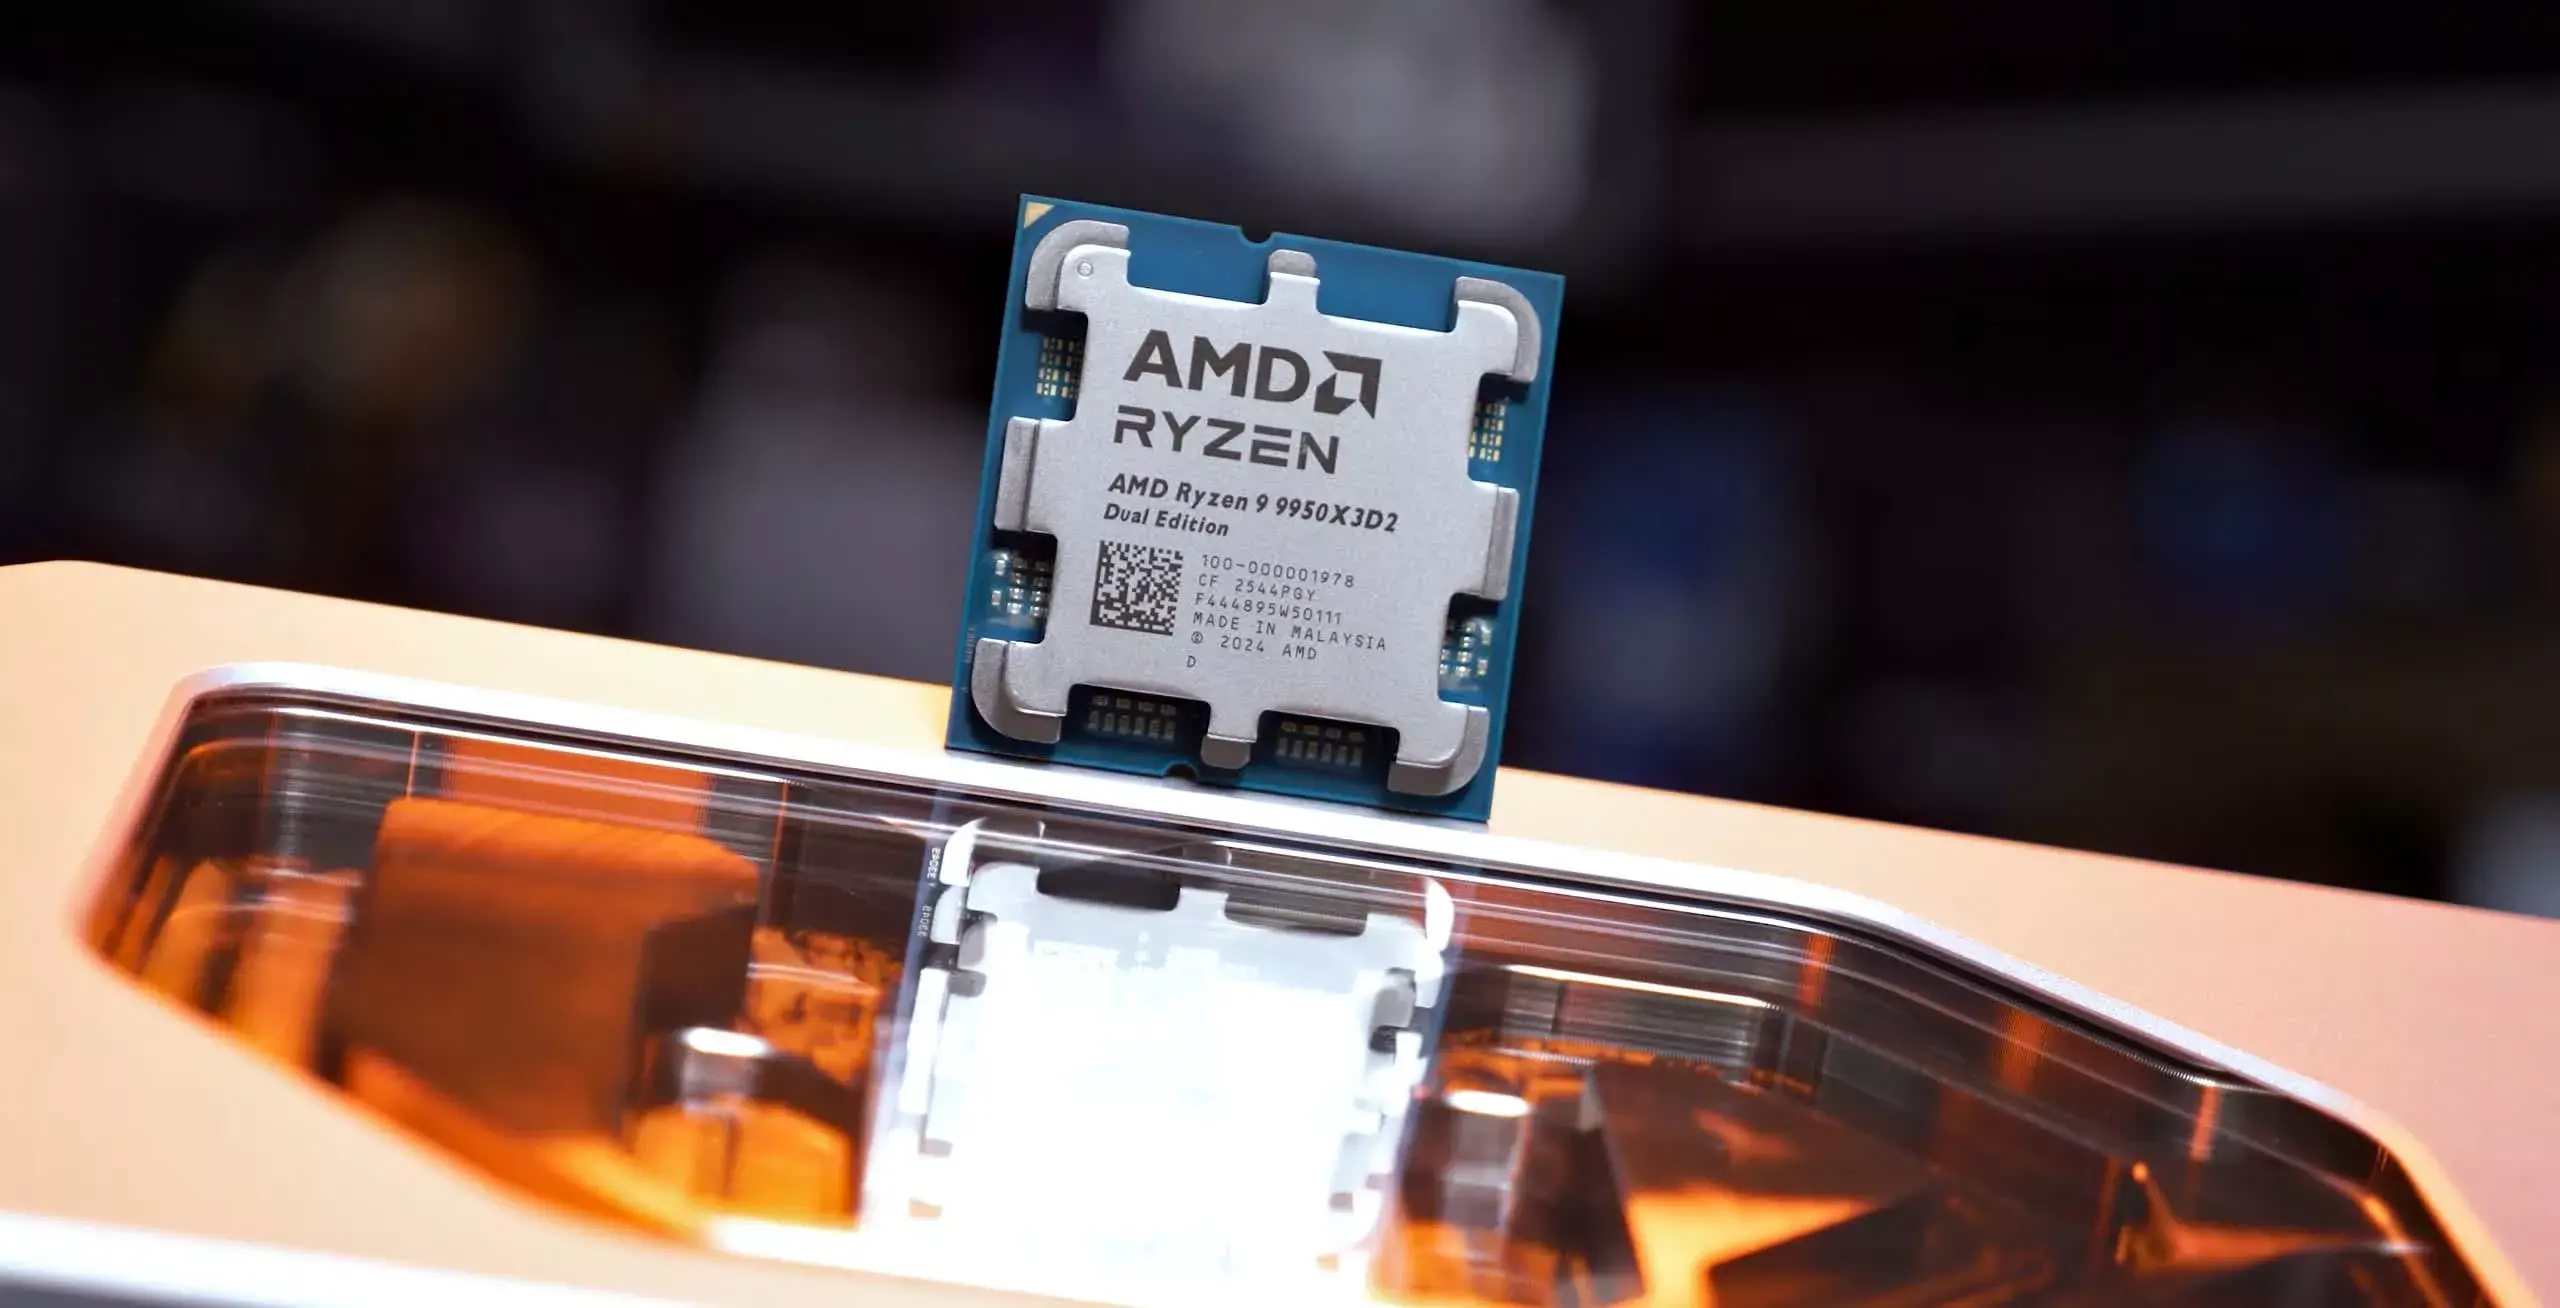
For instance, a Ryzen 9 9950X combines two 8-core compute chiplets with a separate I/O die that handles reminiscence, PCIe and USB.
Smaller dies are cheaper to make, since a single defect ruins much less silicon, and every bit could be constructed on no matter manufacturing course of fits it finest. The trade-off is communication: knowledge touring between chiplets takes longer than knowledge staying on one die, which is why software program and schedulers generally have to hold associated threads on the identical chiplet.
Superior packaging strategies like Intel’s Foveros and AMD’s 3D V-Cache go a step additional by stacking dies on prime of one another.
Bodily Design: From Blueprint to Silicon
Most of this text has targeted on the architectural design of a CPU since that is the place a lot of the complexity is. Nonetheless, this all must be created in the true world and that provides one other stage of complexity.
So as to synchronize all of the elements all through the processor, a clock sign is used. Trendy desktop processors usually run between 3GHz and 5GHz, with the quickest chips boosting to round 6GHz or extra. That is a modest improve over the previous decade, as a lot of the efficiency beneficial properties have come from elsewhere. At every of those cycles, the billions of transistors inside a chip are switching on and off.
Clocks are crucial to make sure that as every stage of the pipeline advances, all of the values present up on the proper time. However clock velocity alone would not decide how briskly a CPU is.
Efficiency comes all the way down to clock velocity multiplied by what number of directions the core can full per clock cycle (IPC). Every thing we have lined, from wider decoders and a number of ALUs to greater caches and higher department predictors, exists to lift IPC. That is why a contemporary core working at 5GHz is a number of occasions quicker than one from a decade in the past working at the same velocity.
Every thing we have lined, from wider decoders and a number of ALUs to greater caches and higher department predictors, exists to lift IPC.
Growing the clock frequency by way of overclocking will make the chip quicker, however will even improve energy consumption and warmth output. Today, CPUs deal with most of that on their very own. Increase algorithms continuously modify clock speeds and voltages primarily based on temperature, energy draw and workload, pushing every chip near its limits proper out of the field and with none handbook intervention. That leaves far much less headroom for handbook overclocking than there was once.
Warmth is a CPU’s worst enemy, that half hasn’t modified. Trendy chips are designed to run scorching, and so they mechanically throttle their clocks in the event that they attain their temperature restrict, usually round 95 to 105°C. Lengthy-term harm comes from the mixture of warmth, voltage and present, which slowly wears down the microscopic transistors and wiring.
Because of this desktop CPUs include warmth spreaders. The precise silicon dies of a CPU could solely take up 20% of the floor space of a bodily machine. Growing the footprint permits the warmth to be unfold extra evenly to a heatsink. It additionally permits extra contacts for interfacing with exterior elements.
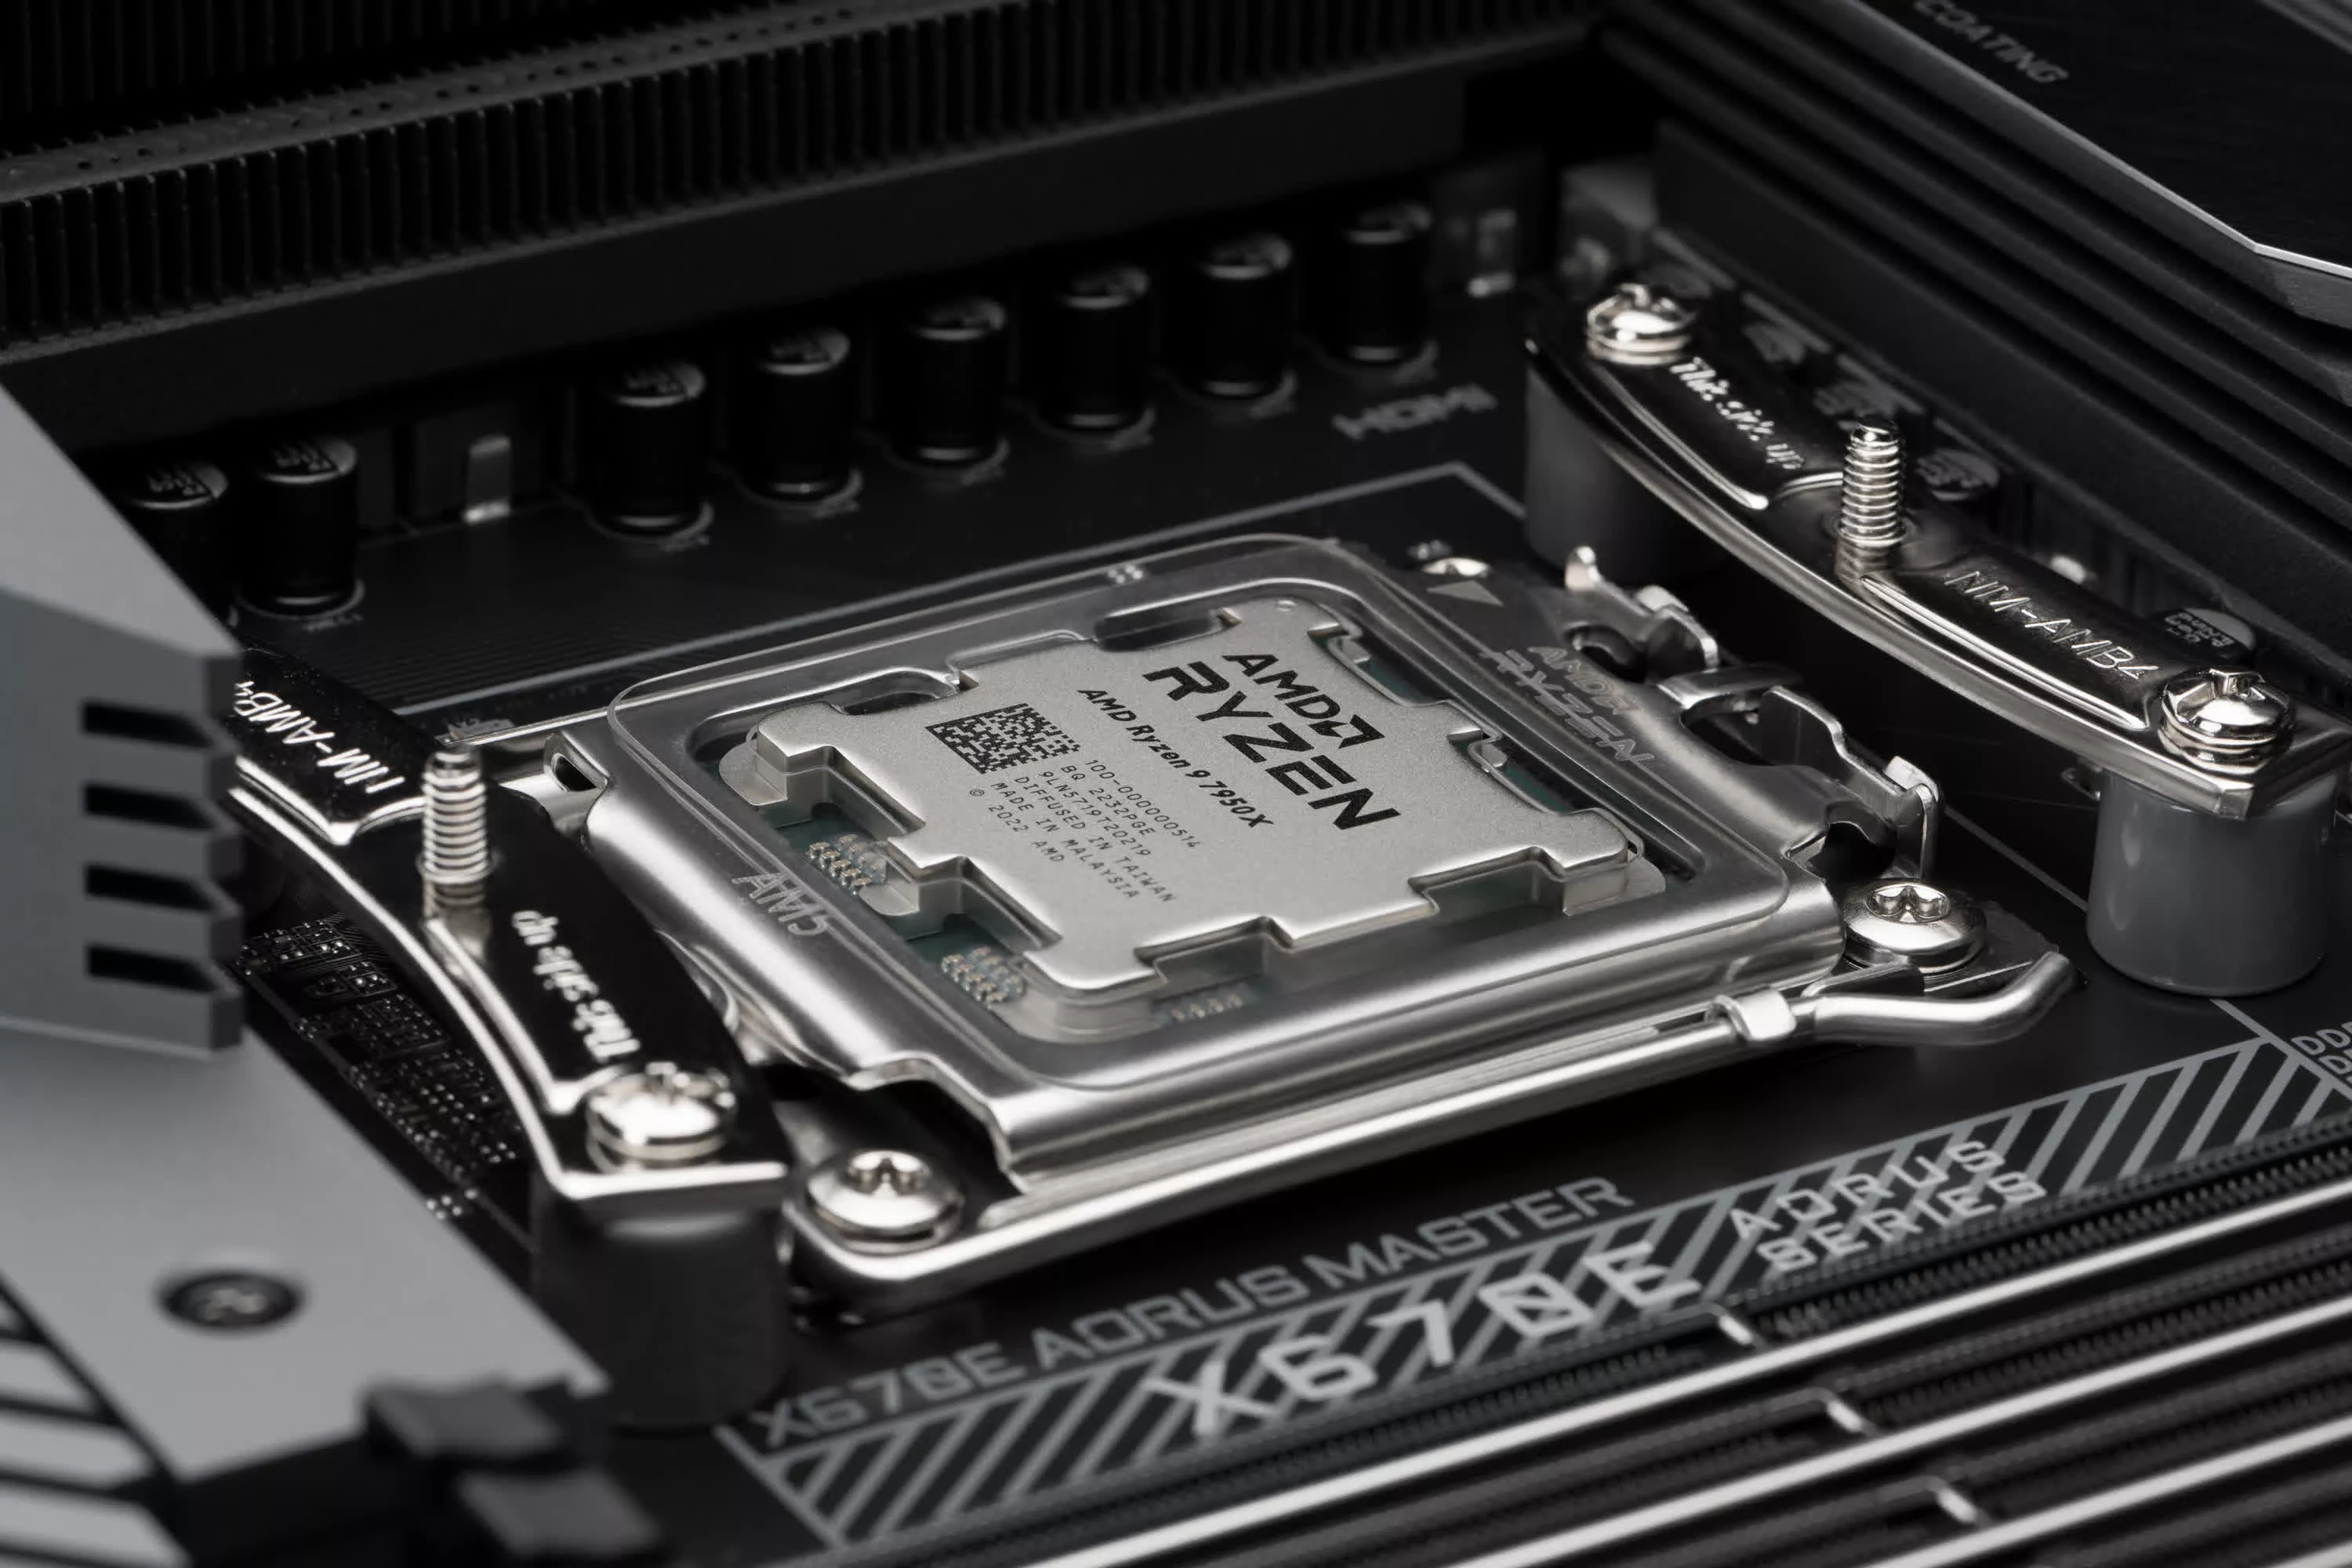
Trendy desktop CPUs have effectively over a thousand electrical contacts on the again. AMD’s AM5 socket makes use of 1,718 and Intel’s LGA 1851 socket makes use of 1,851. Each now use the LGA design, the place the CPU has flat pads and the pins are within the motherboard socket as a substitute.
Laptop computer chips are soldered on to the motherboard utilizing a grid of tiny solder balls, usually numbering effectively over a thousand as effectively. Whatever the design, round half of them are dedicated to energy supply and the remaining are used for knowledge. This contains communication with the RAM, chipset, storage, PCIe gadgets, and extra.
With high-performance CPUs drawing upwards of 200 amps at full load, they want tons of of contacts to unfold out the present draw evenly. The contacts are normally gold plated to enhance electrical conductivity. Totally different producers use completely different preparations of contacts all through their many product strains.
The transistors themselves hold shrinking and altering form, too. The newest manufacturing processes from TSMC and Intel are transferring from FinFET transistors to gate-all-around designs, the place the gate absolutely wraps the channel for higher management and fewer leakage. Intel’s 18A course of, utilized in its Panther Lake chips, additionally introduces bottom energy supply, which strikes the facility wiring to the again of the silicon wafer and leaves the entrance free for knowledge indicators. For a a lot deeper have a look at how chips are manufactured, try Half 3 of our CPU design collection.
Placing It All Collectively: Inside AMD’s Zen 5
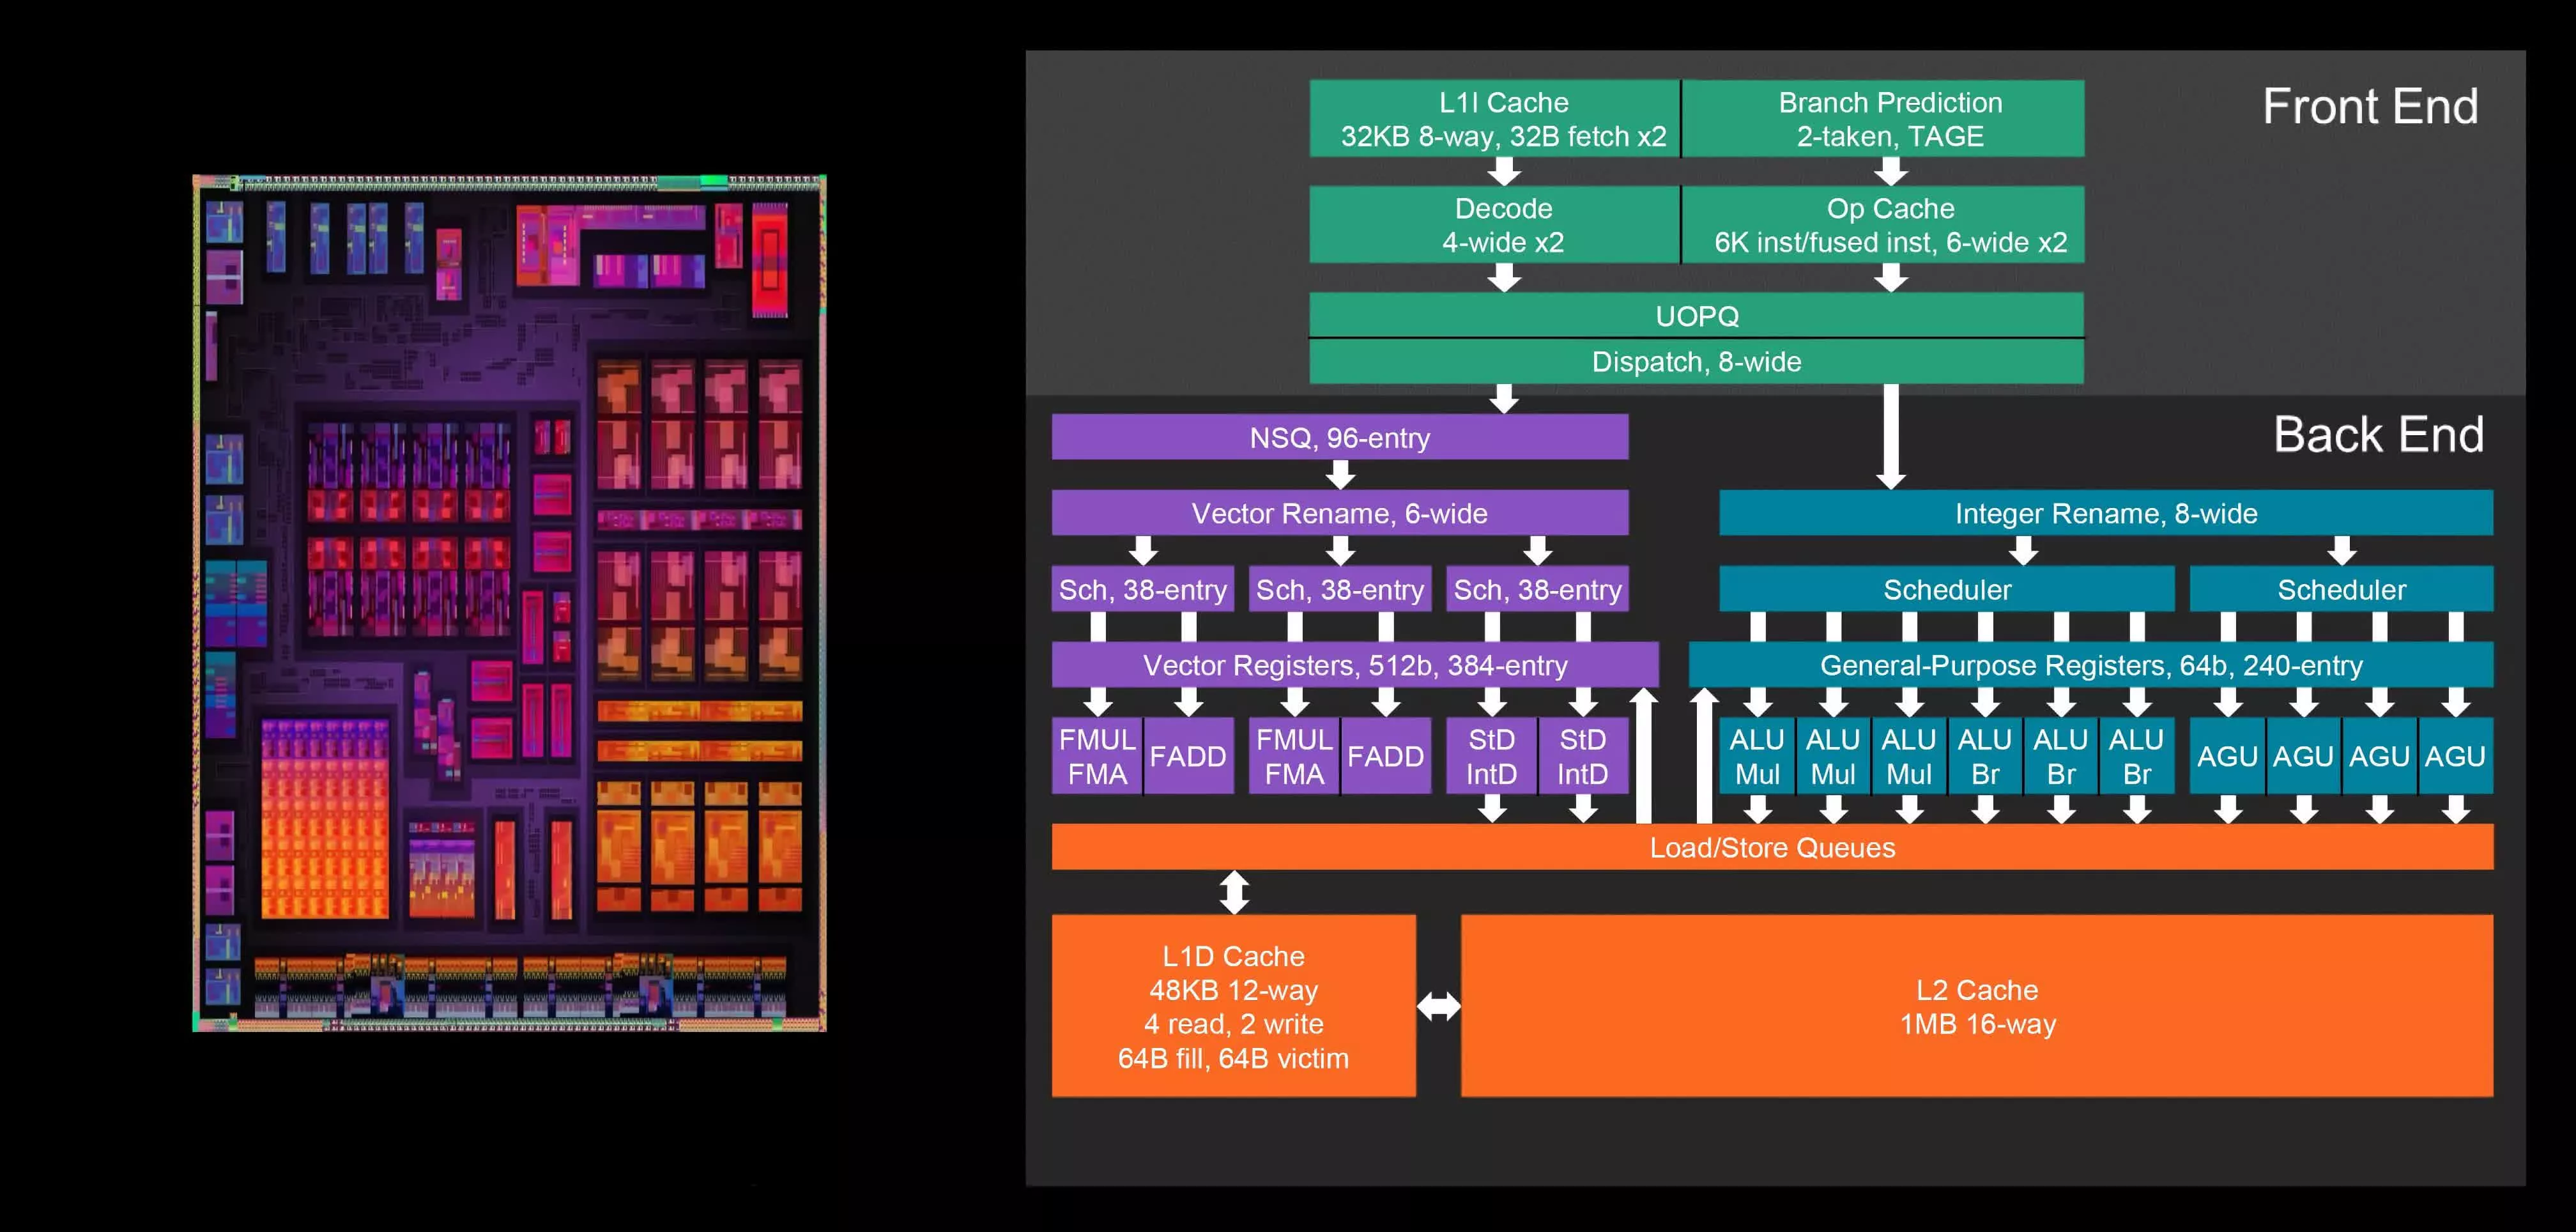
To wrap issues up, we’ll take a fast have a look at the design of a contemporary CPU core: AMD’s Zen 5, discovered within the Ryzen 9000 collection. AMD has printed detailed diagrams of the core, and almost each idea we have lined reveals up in it.
Beginning on the prime, the department predictor runs forward of every part else, guessing the place this system is headed and telling the entrance finish which directions to fetch. These directions come from a 32KB L1 instruction cache, with assist from the TLB buffer, a small cache that remembers current translations between the reminiscence addresses a program makes use of and their precise bodily areas in RAM.
From there, the directions undergo two separate decode clusters that work in parallel, every turning x86 directions into micro-ops. Code that has run just lately can skip decoding solely and are available straight out of the micro-op cache. Both means, as much as eight micro-ops per cycle are handed alongside to the following stage.
AMD’s Zen 5 core, as utilized in Ryzen 9000 desktop processors
That is the place the out-of-order equipment takes over. The micro-ops undergo register renaming and are entered right into a 448-entry reorder buffer, which tracks each instruction. They then wait in schedulers till their enter knowledge is prepared. The precise workings of those are a bit complicated (assume graduate-level college course), however they’re what let the core decide probably the most well timed instruction to execute subsequent whereas retaining leads to the proper order.
As soon as an instruction is prepared, it is despatched to one of many execution models. Zen 5 has six integer ALUs, 4 tackle era models for reminiscence operations, and a floating-point and vector unit that may course of full 512-bit AVX-512 directions. Reminiscence operations are served by a 48KB L1 knowledge cache, backed by a 1MB L2 cache per core and a 32MB L3 shared by all eight cores on the chiplet.
The output outcomes can be saved, the instruction can be retired in program order, and the CPU is now prepared to begin on the following instruction. That is about it!
Whereas this text was not meant to be a definitive information to precisely how each CPU works, it ought to offer you a good suggestion of their interior workings and complexities (!). Frankly, nobody outdoors of Intel, AMD or Apple is aware of each element of how their CPUs work. Every part of this text represents a whole subject of analysis and growth so the data introduced right here simply scratches the floor.
Maintain Studying
In case you are eager about studying extra about how the assorted elements lined on this article are designed, try Half 2 of our CPU design collection. In the event you’re extra eager about studying how a CPU is bodily made all the way down to the transistor and silicon stage, try Half 3.